What if the same Python code could call a hosted model or a model on our own GPU, and only the address changed? We tried it. On 200 bank card messages, hosted Jev 1.13 picked the right intent 97% of the time. Laya, running on our RTX 5090, got 87.5%. But here's the twist: Laya answered a single request in 20.5 ms, and Jev took 654 ms.
Jev and Laya are decision models. They do not write text. We give them some text, called the state, and a question with a fixed list of answers. In simple words, they fill in a multiple choice sheet and tell us how sure they are about each option. Jev is TypeSafe's hosted model. Laya is an open-weights model from Convai Innovations that runs on our own machine.
In this blog, we will learn how to point one script at both models, how they compare on the same 200 messages, how fast each one answers, and how much we can trust Laya's confidence on a store inbox.
Our Test Setup
Let me tabulate the setup for your better understanding:
| Item | Jev | Laya |
|---|---|---|
| Model that answered | typesafe/jev-1.13-20260917 |
laya:en (ModernBERT-large) |
| Where it runs | Hosted, reached through OpenRouter | Our RTX 5090 desktop, on cuda:0 |
| Server | TypeSafe's API | Ollaya 0.9.0 on http://localhost:11435 |
| Client | TypeSafe SDK | The same TypeSafe SDK |
The notebook ran on 4 October 2026, the date stamped in Ollaya's responses. Ollaya is a small local server for Laya, a bit like Ollama is for chat models. It speaks the same request format as hosted Jev, and that is what makes this test fair: the question code is the same for both models.
One Script for Both Models
The TypeSafe SDK has three question types. A Choice picks one option from a list. A Score picks a level on a scale. A Noul is a yes or no question, and its answer is the probability of yes. Let's see the imports as below:
import asyncio, time
import httpx
import pandas as pd
from dotenv import load_dotenv
from typesafe_sdk import TypeSafeClient, AsyncTypeSafeClient, Choice, Score, Noul

load_dotenv()
OLLAYA = "http://localhost:11435"
load_dotenv() reads our .env file. That file holds TYPESAFE_BASE_URL and TYPESAFE_API_KEY, and we point them at OpenRouter. So TypeSafeClient() with no arguments talks to hosted Jev.
For Laya, only three things change: base_url, api_key and model. Ollaya ignores the key, but the SDK will not start without one, so we pass the word "local". Let's ask both models the same yes or no question:
local = TypeSafeClient(base_url=OLLAYA, api_key="local", model="laya")
jev = TypeSafeClient()

REFUND = Noul(instructions="The customer asks for money back.")
state = "I was charged twice for order 20966. Please refund the second payment today."

local.system_one(state, {"refund": REFUND})SystemOneResponse(model='laya:en', usage=Usage(input_tokens=49, output_tokens=0), answers={'refund': NoulAnswer(type='noul', noul=0.8915)})Here, we can see Laya gave a probability of 0.8915 that the customer wants money back. Now the same call on hosted Jev:
jev.system_one(state, {"refund": REFUND})SystemOneResponse(model='typesafe/jev-1.13-20260917', usage=Usage(input_tokens=293, output_tokens=20), answers={'refund': NoulAnswer(type='noul', noul=0.98)})Jev said yes with 0.98. Both models agree, and the answer comes back in the same shape. Our code does not care which model is on the other end.
The Bank Card Question
Now we need a harder job. We use 200 real bank card messages from the Banking77 dataset, with 10 intents and typos included. Each message has a gold label, the intent a person gave it. Let's load them as below:
cards = pd.read_csv("data/card_messages.csv")
cards.head()| id | text | intent | |
|---|---|---|---|
| 0 | 1 | I'm starting to think my card is lost because ... | card_arrival |
| 1 | 2 | What do I need to do to change my PIN? | change_pin |
| 2 | 3 | What do I do if I think my card was improperly... | compromised_card |
| 3 | 4 | I cannot find my credit card. | lost_or_stolen_card |
| 4 | 5 | How can I change my Tholepin ? | change_pin |
Here, we can see real customer wording, typos and all, like "Tholepin" for PIN. We write one Choice question with a short description for every option. The description tells the model what kind of message belongs there. Let's see the code as below:
CARD_INTENT = Choice(
    instructions="What does the bank customer need help with?",
    criteria={
        "activate_my_card": "activating a card that has arrived",
        "card_about_to_expire": "a card that expires soon, getting a replacement before expiry",
        "card_arrival": "a new card that has not arrived yet",
        "card_not_working": "a card that does not work at all",
        "card_payment_fee_charged": "an unexpected fee on a card payment",
        "card_payment_wrong_exchange_rate": "a wrong exchange rate on a card payment abroad",
        "change_pin": "changing or resetting the PIN",
        "compromised_card": "someone else may have used the card or its details",
        "declined_card_payment": "a card payment that was declined",
        "lost_or_stolen_card": "a card that is lost or stolen",
    },
)
Both models get this exact question. Nothing else changes between them.
Which Model Is More Accurate?
We send all 200 messages to each model at the same time with asyncio.gather. For that we need the async clients. alocal is AsyncTypeSafeClient(base_url=OLLAYA, api_key="local", model="laya"), the async twin of our local client, and ajev is the hosted one. We also time each batch, so we get speed and accuracy from the same run:
ajev = AsyncTypeSafeClient()

start = time.perf_counter()
laya_results = await asyncio.gather(*[alocal.system_one(t, {"intent": CARD_INTENT}) for t in cards.text])
laya_seconds = time.perf_counter() - start

start = time.perf_counter()
jev_results = await asyncio.gather(*[ajev.system_one(t, {"intent": CARD_INTENT}) for t in cards.text])
jev_seconds = time.perf_counter() - start

laya_results[0].model, jev_results[0].model('laya:en', 'typesafe/jev-1.13-20260917')Here, we can see the exact models that answered: Laya's English checkpoint and the dated Jev 1.13 build 20260917. Now we score both against the gold labels:
cards["laya"] = [r.answers["intent"].choice for r in laya_results]
cards["jev"] = [r.answers["intent"].choice for r in jev_results]

pd.DataFrame({
    "accuracy": [(cards.laya == cards.intent).mean(), (cards.jev == cards.intent).mean()],
    "seconds_for_200": [laya_seconds, jev_seconds],
}, index=["laya", "jev"])| accuracy | seconds_for_200 | |
|---|---|---|
| laya | 0.875 | 2.275112 |
| jev | 0.970 | 2.078333 |
Here, we can see Jev got 0.970 and Laya got 0.875 on the same 200 messages. That is 97% against 87.5%. Let me tabulate every number from this run for your better understanding:
| Measure | Jev 1.13, hosted | Laya, local RTX 5090 |
|---|---|---|
| Accuracy, 200 bank card messages, 10 intents | 0.970 (97%) | 0.875 (87.5%) |
| One request, wall time | 654 ms, through OpenRouter, network included | 20.5 ms |
| All 200 requests at once | 2.08 s | 2.28 s |
Where Laya Loses Points
So where does the gap come from? We break the accuracy down by intent:
cards.assign(laya_ok=cards.laya == cards.intent, jev_ok=cards.jev == cards.intent).groupby("intent")[["laya_ok", "jev_ok"]].mean()| intent | laya_ok | jev_ok |
|---|---|---|
| activate_my_card | 0.95 | 0.95 |
| card_about_to_expire | 0.80 | 0.85 |
| card_arrival | 0.55 | 1.00 |
| card_not_working | 0.80 | 0.95 |
| card_payment_fee_charged | 0.95 | 1.00 |
| card_payment_wrong_exchange_rate | 0.90 | 0.95 |
| change_pin | 1.00 | 1.00 |
| compromised_card | 0.85 | 1.00 |
| declined_card_payment | 0.95 | 1.00 |
| lost_or_stolen_card | 1.00 | 1.00 |
Here, we can see one intent does most of the damage. On card_arrival, Laya got 0.55 and Jev got 1.00. Laya sent many "where is my new card" messages to lost_or_stolen_card. For example, "How do I track my card?" and "still waiting on that card" both went to lost_or_stolen_card with Laya, and to card_arrival with Jev.
That makes sense once we read the messages. A card that never arrived does sound a bit like a lost card. Jev separates the two. Laya does not, at least not with these option descriptions.
Which Model Is Faster?
Speed has two sides. One user waits for one answer. A batch job waits for all of them. Let's time one request first, the way a single user would feel it:
%time local.system_one(cards.text[0], {"intent": CARD_INTENT}).answers["intent"].choiceCPU times: total: 0 ns
Wall time: 20.5 ms
'lost_or_stolen_card'Laya answered in 20.5 ms on our GPU. Now the same call on hosted Jev:
%time jev.system_one(cards.text[0], {"intent": CARD_INTENT}).answers["intent"].choiceCPU times: total: 0 ns
Wall time: 654 ms
'card_arrival'Jev took 654 ms. This number includes the trip over the internet to OpenRouter and back, not just the model's own work. Notice the answers too. The gold label of this first message is card_arrival, so Jev was right and Laya was wrong, the same pattern we saw in the table above.
Now look back at the batch timings. All 200 at once took Laya 2.28 s and Jev 2.08 s. So when we send many requests at the same time, the gap closes, and Jev was even a little faster. A hosted service can work on many requests in parallel, so the network wait overlaps instead of adding up.
Note
Each timing here is a single run, not an average of many. The 654 ms also depends on where we sit and on OpenRouter's route that day. Treat these as one honest snapshot, not a fixed speed.
Laya on a Store Inbox
Laya is not only for bank messages. Its real strength is that it runs on our own machine, so private text never leaves it. Let's try it on an inbox: 40 labelled emails to a mid-size online home goods store, 5 each of 8 intents. We load them from data/emails.csv into a DataFrame called emails, with a subject, a body and the gold intent for each email.
We write one Choice with a description per option. The state is JSON, so the model reads the subject and the body together:
INTENT = Choice(
    instructions="What does the sender of this email want from the store?",
    criteria={
        "order_status": "a customer asks where an order is or when it will arrive",
        "return_request": "a customer wants to send an item back, exchange it or get a return label",
        "invoice_request": "someone needs an invoice, a receipt or a corrected invoice",
        "partnership": "a business, creator or event proposes working together or buying wholesale",
        "job_application": "someone applies for a job or an internship",
        "spam": "unsolicited marketing, scams and phishing",
        "complaint": "a customer is unhappy about service, quality, a charge or a person",
        "supplier_update": "a supplier announces prices, delays, new products or changes",
    },
)
Now we send all 40 emails at once with the async client and check the accuracy:
alocal = AsyncTypeSafeClient(base_url=OLLAYA, api_key="local", model="laya")

results = await asyncio.gather(*[
    alocal.system_one({"subject": s, "body": b}, {"intent": INTENT})
    for s, b in zip(emails.subject, emails.body)
])
emails["pred"] = [r.answers["intent"].choice for r in results]
emails["confidence"] = [r.answers["intent"].confidence for r in results]
(emails.pred == emails.intent).mean()np.float64(0.875)Here, we can see Laya got 0.875, so 35 of the 40 emails went to the right place. Let's look at the five misses with their confidence:
emails[emails.pred != emails.intent][["subject", "intent", "pred", "confidence"]]| subject | intent | pred | confidence | |
|---|---|---|---|---|
| 15 | Delay on PO 4471, linen napkins | supplier_update | order_status | 0.5382 |
| 23 | New AW catalogue | supplier_update | order_status | 0.4508 |
| 27 | Listing your products on Greenshelf | partnership | spam | 0.8856 |
| 29 | Invoice #INV-88213 overdue, action required | spam | invoice_request | 0.9947 |
| 38 | Promo code didn't work and nobody helps | complaint | spam | 0.5355 |
Three of the five misses sit near 0.5 confidence. So, can confidence tell right answers from wrong ones? Let's compare the average confidence of each group:
emails.groupby(emails.pred == emails.intent).confidence.mean()False 0.680960
True 0.912631
Name: confidence, dtype: float64Here, we can see wrong answers averaged about 0.68 confidence and right answers about 0.91. That is a useful signal. If we send low-confidence emails to a person, we catch most of the misses.
But it is not a perfect signal. The fake "overdue invoice" email is a phishing attempt, and Laya filed it as invoice_request with 0.9947 confidence. A confidence cut-off would never stop that one. This is why we test on our own labelled data before trusting any cut-off.
Which One Should We Use?
Let me tabulate the answer from this run:
| If we need | Pick | Why |
|---|---|---|
| The most right answers on this card question | Jev 1.13 | 0.970 against 0.875 |
| The fastest single answer | Laya on a local GPU | 20.5 ms against 654 ms |
| A big batch sent all at once | Either | 2.08 s and 2.28 s for 200 messages |
| Text that must stay on our machine | Laya | it never leaves the local server |
Since the code is the same for both, we do not have to choose once and for all. We can start with one and switch by changing base_url, api_key and model.
Limits of This Test
This is one desktop, one network and one run:
- The single-request times come from one
%timecall each, not an average. - Jev's time includes the network to OpenRouter. Calling from another place, or through TypeSafe directly, could be faster or slower.
- We wrote the option descriptions once and did not tune them for either model. Different wording can change both scores.
- 200 messages and 40 emails are small samples. A gap of a few messages could move on another run.
If you run Jev and Laya on your own data, please share your accuracy and your time per request in the comments.
Conclusion
This is how hosted Jev 1.13 and Laya on a local RTX 5090 compare on the same question. We used one TypeSafe SDK script for both, and only the address, key and model name changed. On 200 bank card messages, Jev was more accurate, 0.970 against 0.875, mostly because Laya mixed up cards that had not arrived with lost cards. Laya answered one request in 20.5 ms against 654 ms for Jev, but with all 200 sent at once the two finished in about the same time.
Key takeaways:
- Ollaya serves Laya with the same request format as hosted Jev, so one script runs both.
- Jev 1.13 scored 0.970 and Laya 0.875 on the same 10-intent card question.
- Most of Laya's misses came from one intent:
card_arrivalat 0.55 against 1.00 for Jev. - Local Laya wins on one request; under load the network wait overlaps and the gap closes.
- On the store inbox, wrong answers averaged about 0.68 confidence against 0.91 for right ones, but one phishing email was wrong at 0.9947.
Next steps:
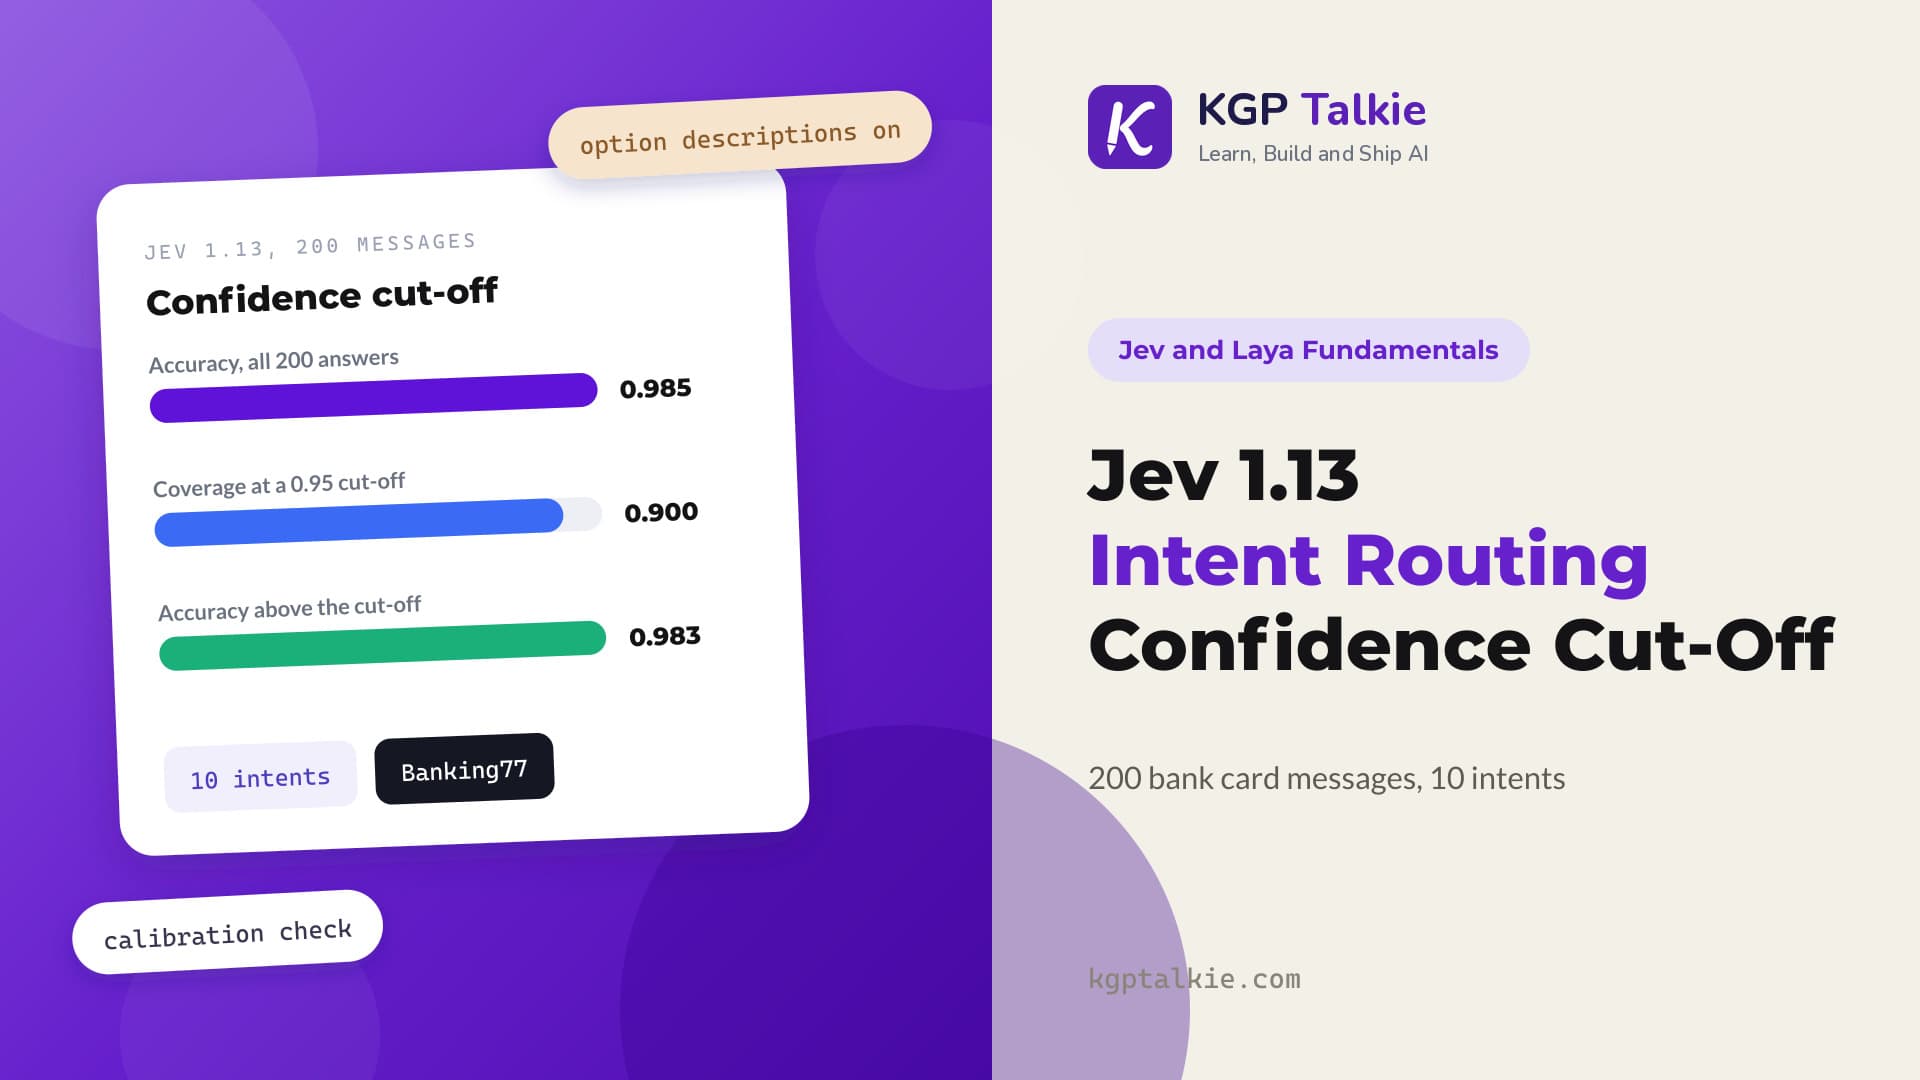
- Read Jev 1.13 intent routing on 200 bank messages to test Jev before launch and pick a confidence cut-off.
- See Laya 421M vs Qwen3.5 0.8B vs Qwen2.5 0.5B for Laya against small LLMs on a MacBook Pro M5 Max.
- Use the Ollama setup guide if you are new to running models on your own machine.
In short, we sent the same 10-intent question to hosted Jev and to local Laya, and measured how often each was right and how long each took.