LLM Benchmarking
Head to head model runs on local hardware, architecture teardowns read straight from the weights, inference tuning, and the test bench every number comes from.
LLM Benchmarking Tutorials (18)
Browse, search, and work through all available articles for this category.
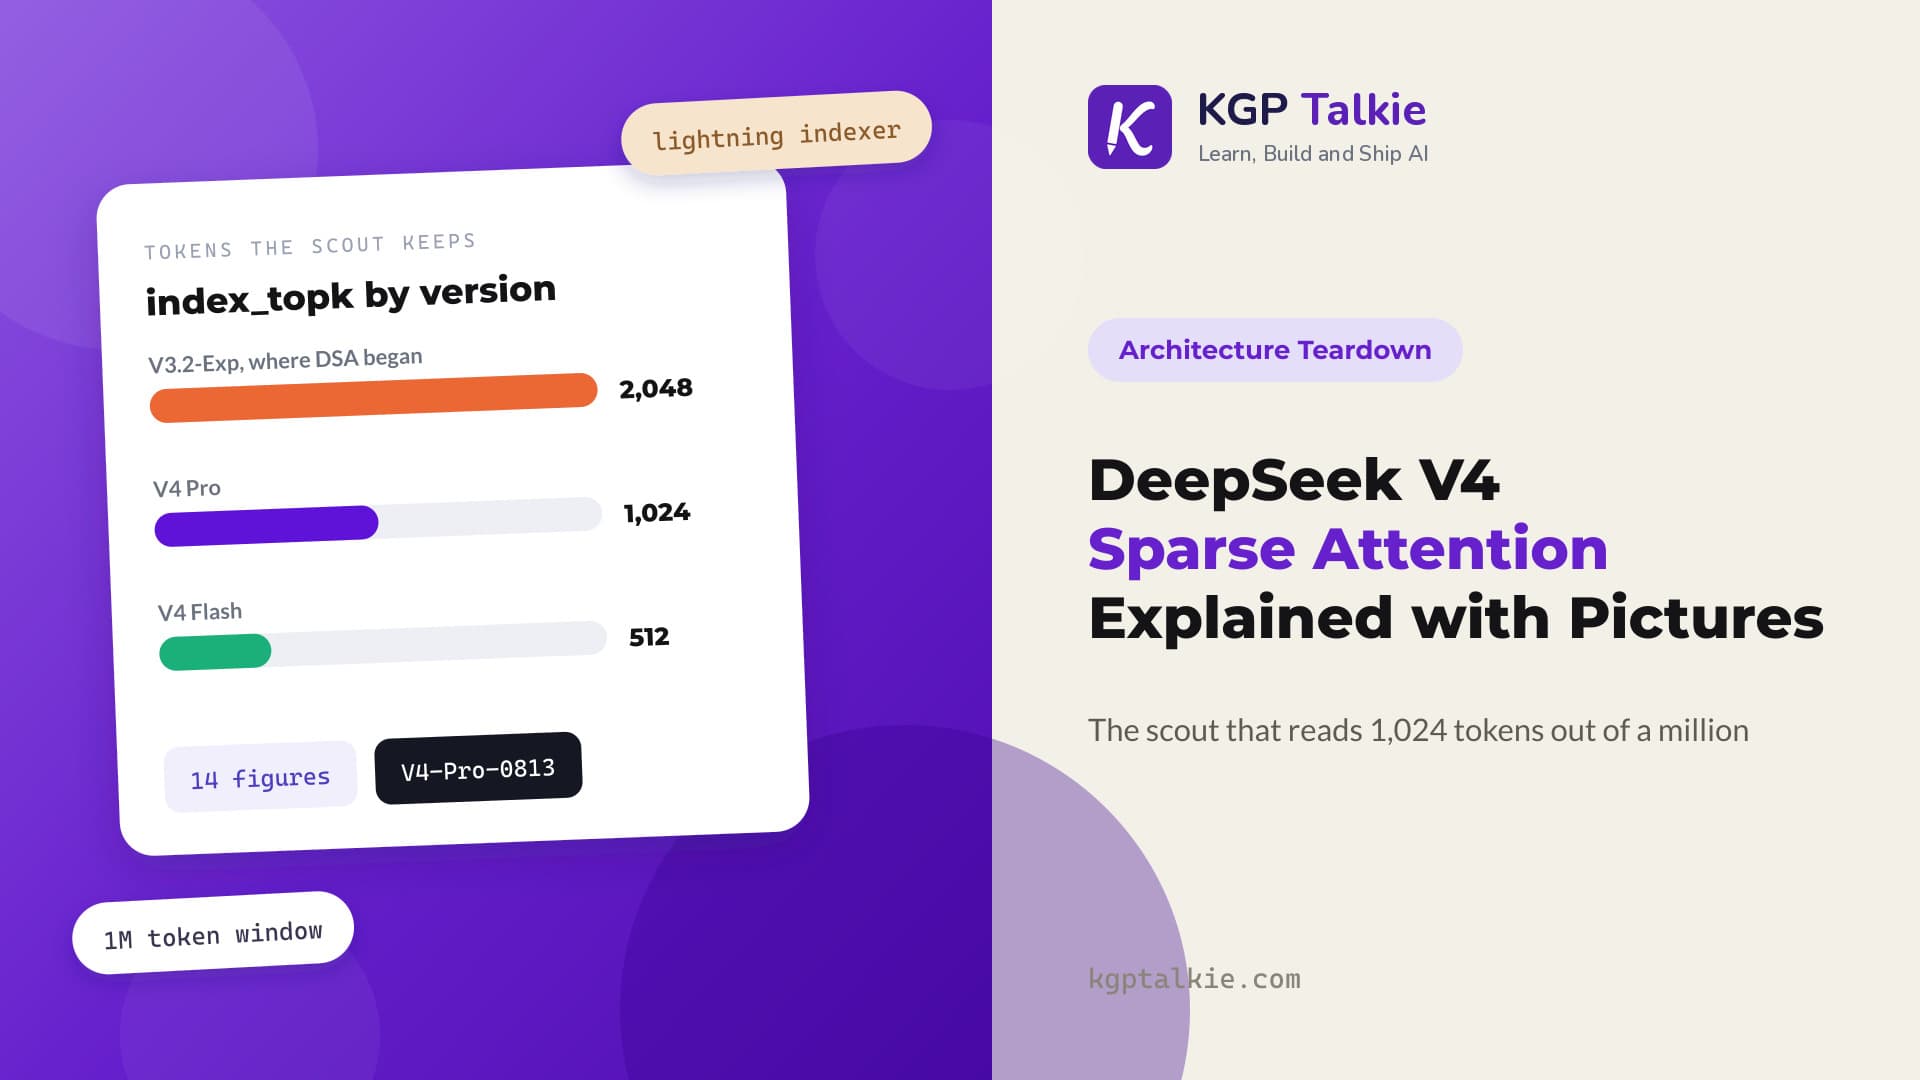
DeepSeek V4.1 Sparse Attention Explained with Pictures
A picture by picture walk through the sparse attention inside DeepSeek V4.1 Flash: the lightning indexer, the 512 entry pick, and how CSA2 shares one pick across many layers.
Read Tutorial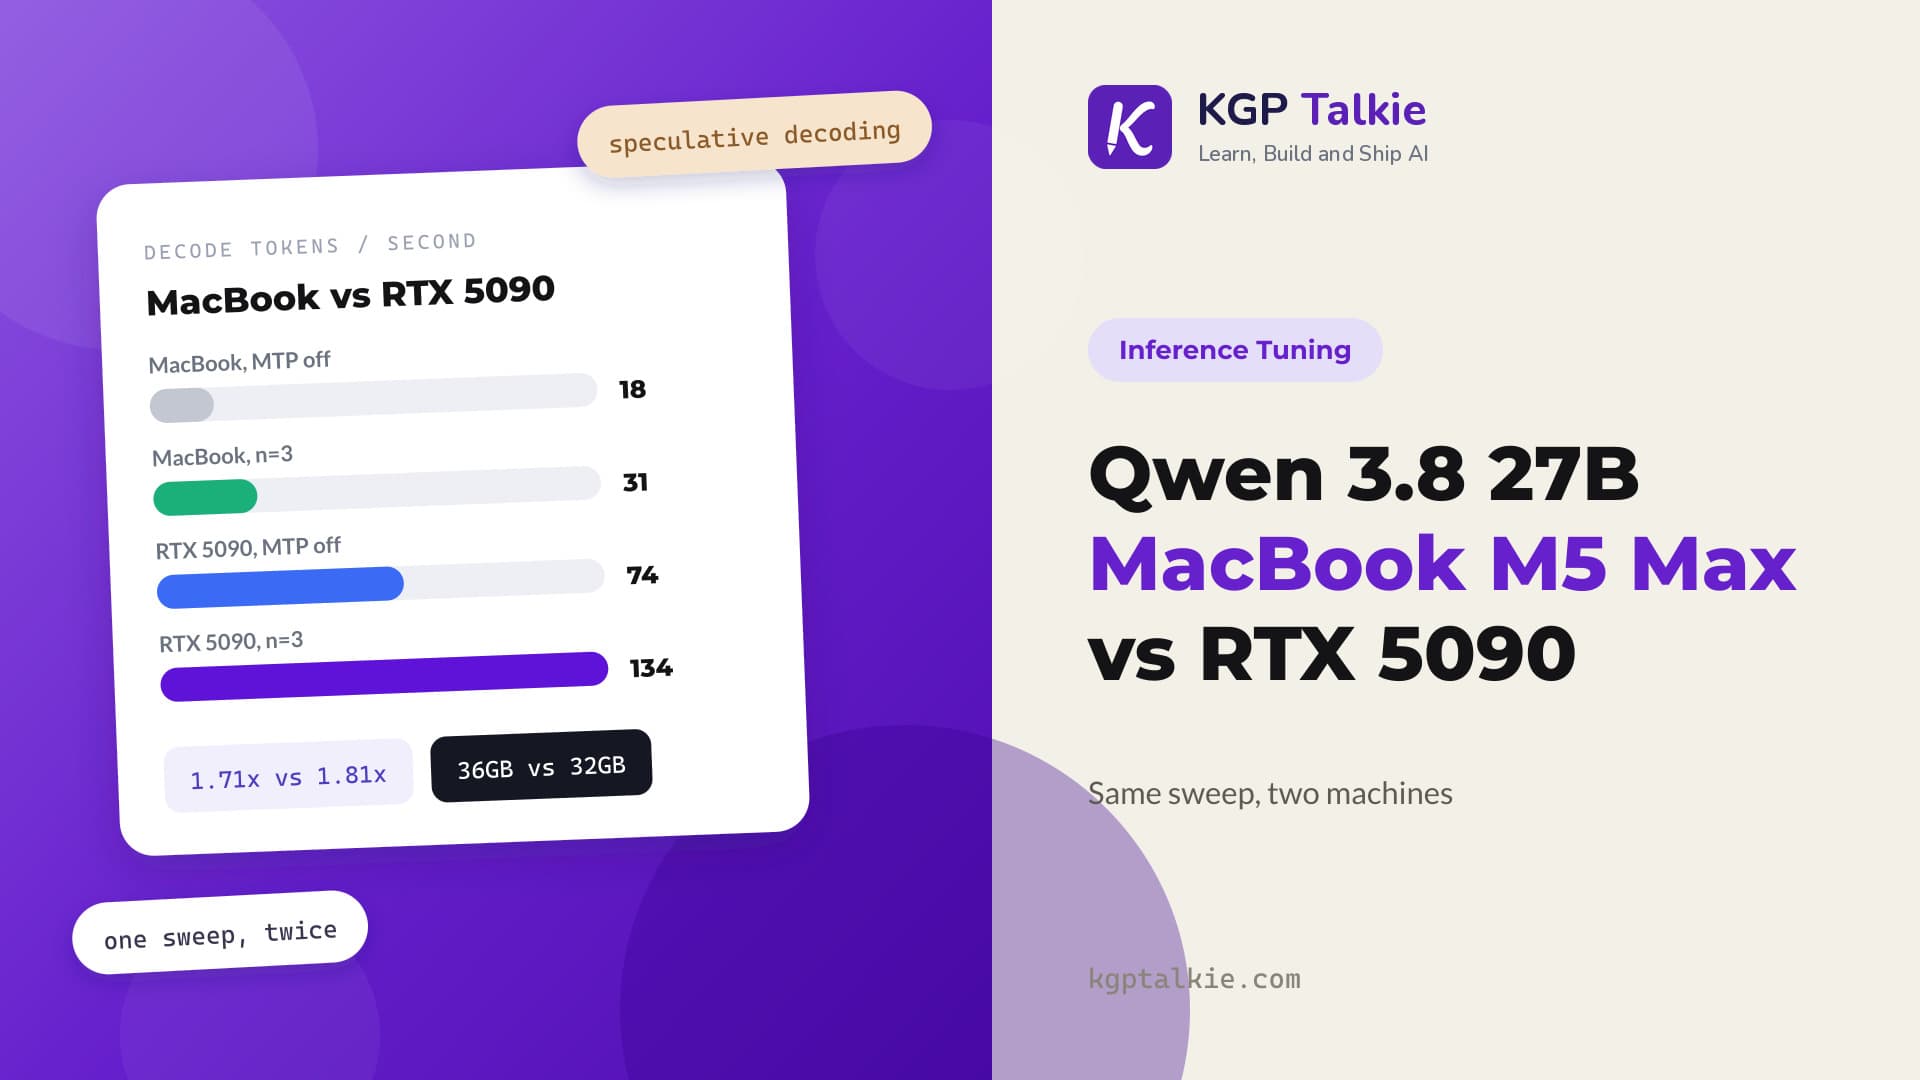
Qwen 3.8 27B Benchmark on a MacBook Pro M5 Max vs RTX 5090
We ran the same Qwen 3.8 27B sweep on a MacBook Pro M5 Max and an RTX 5090. The desktop decodes about four times faster, but the draft head wins on both, and only one machine stalls.
Read Tutorial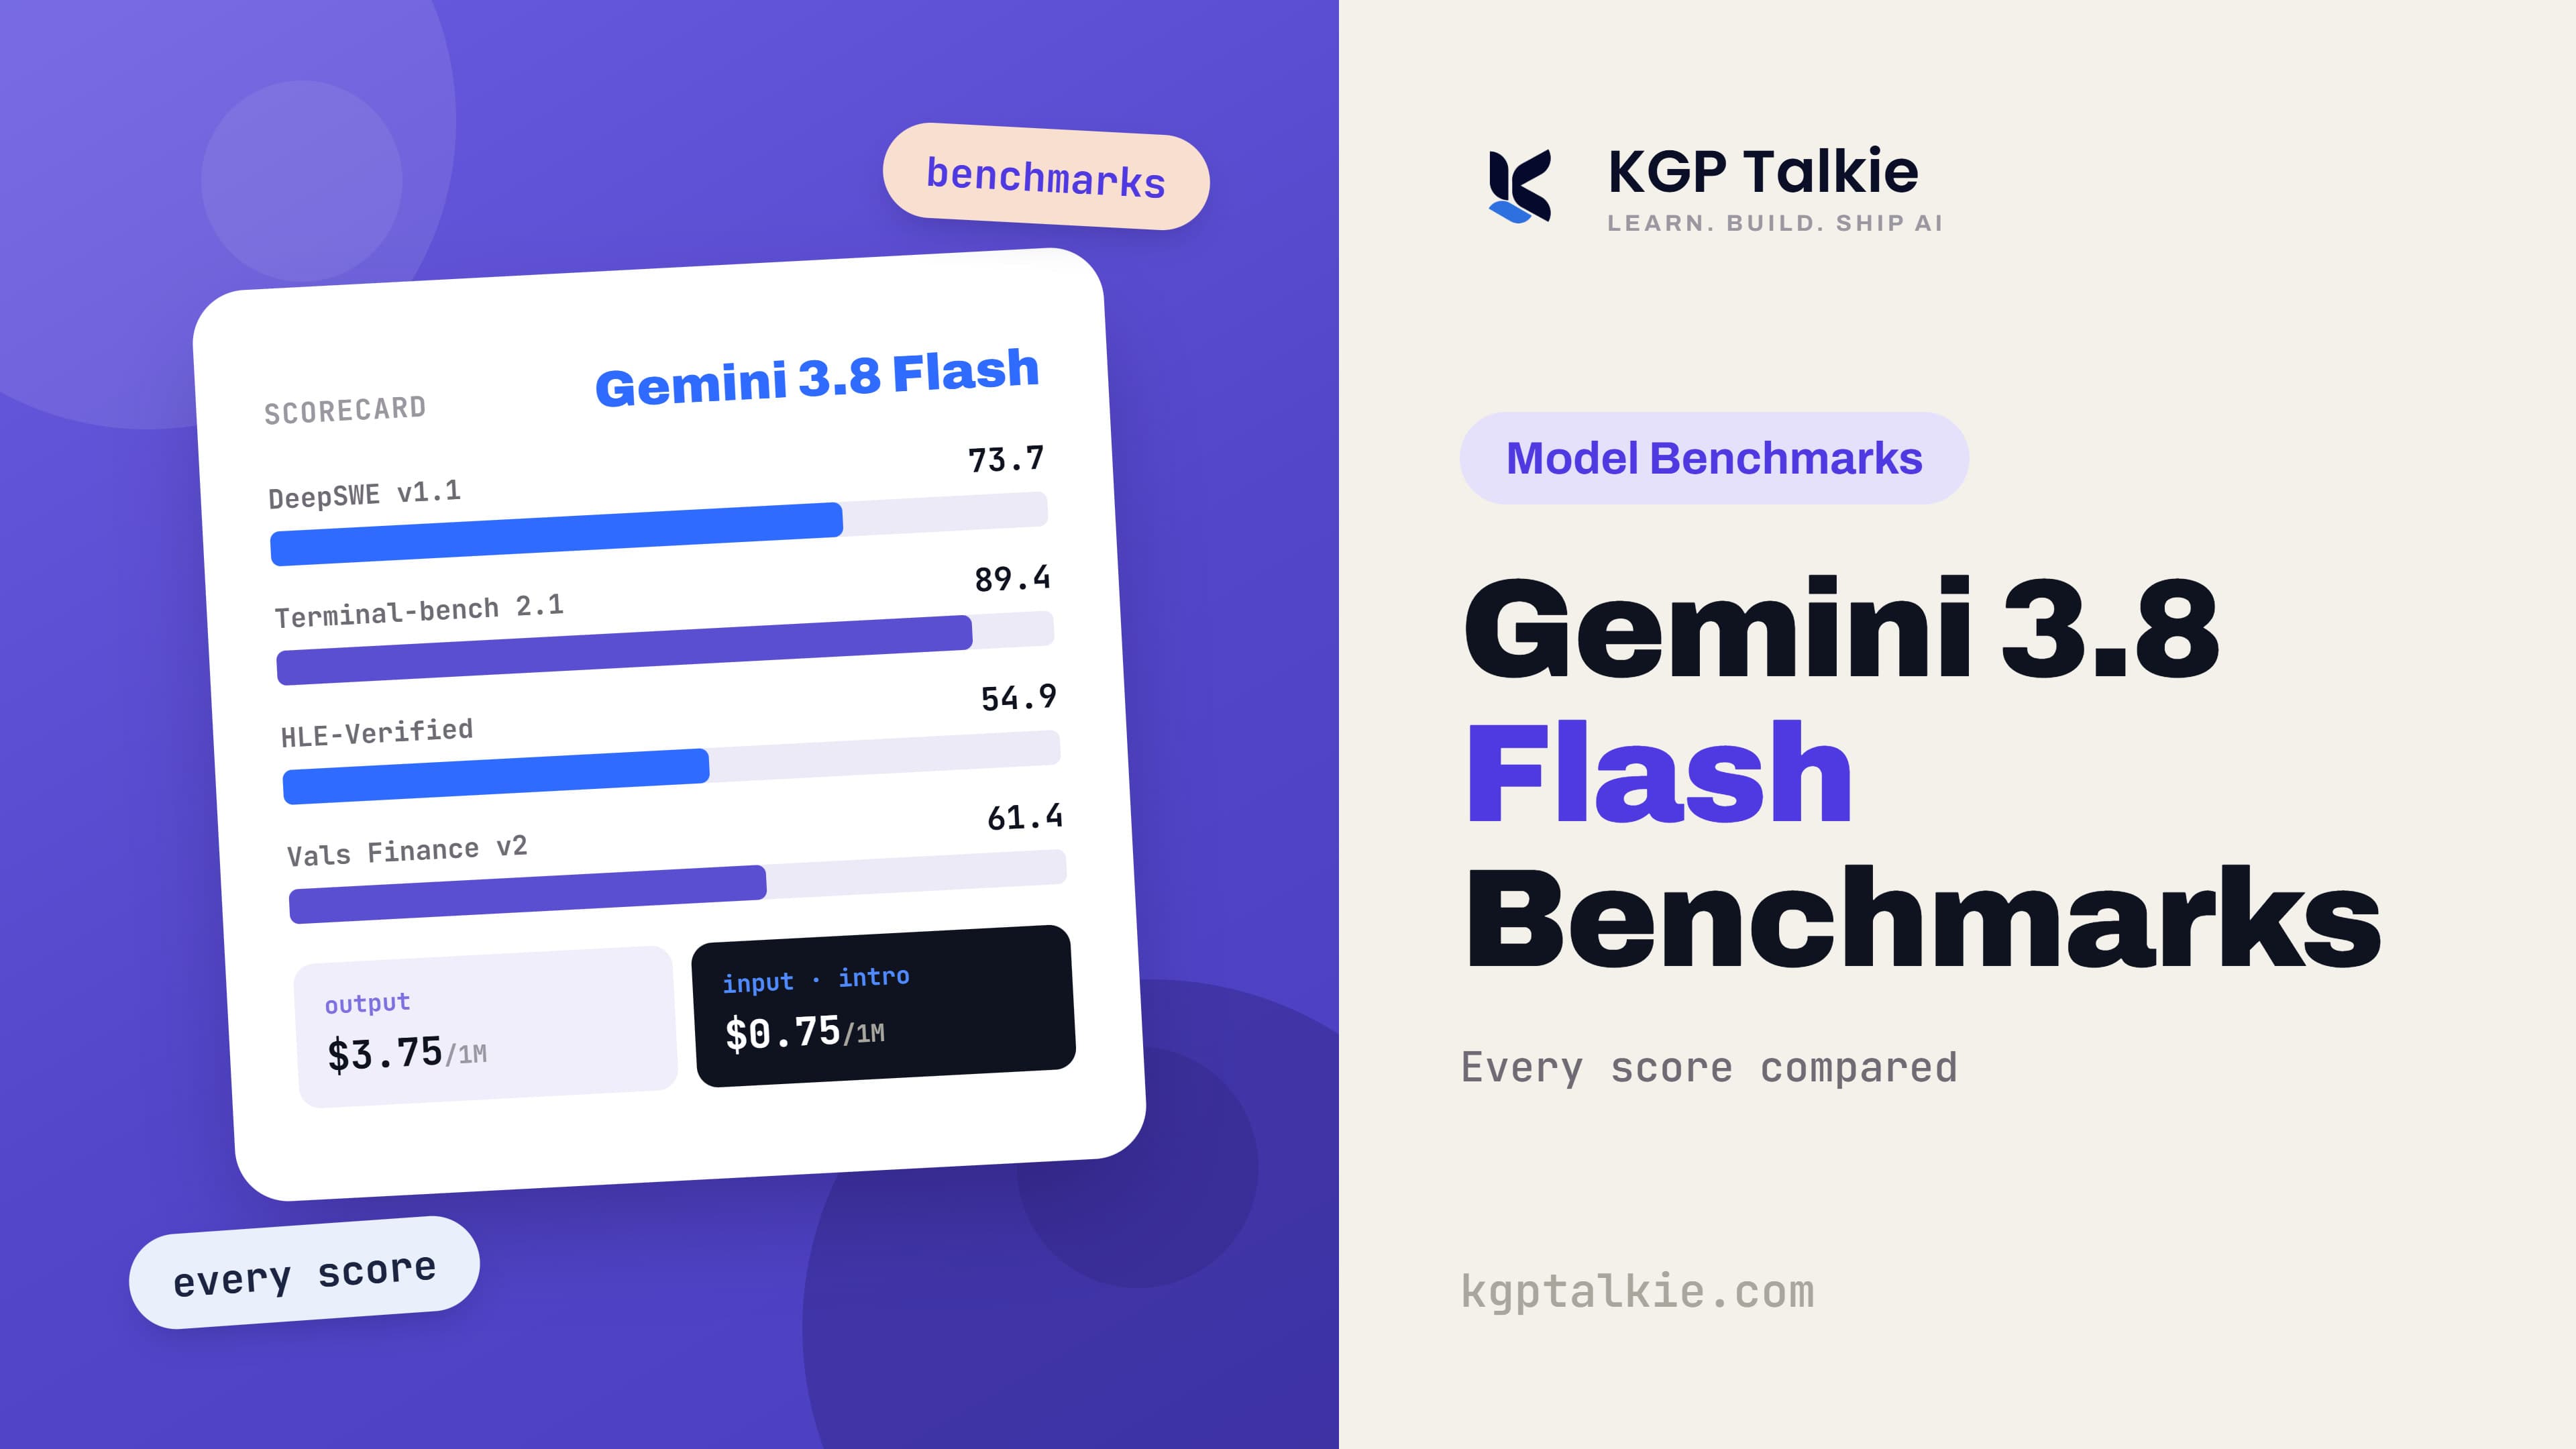
Gemini 3.8 Flash Benchmarks: Every Score Compared
Every Gemini 3.8 Flash benchmark score in one table, compared with Gemini 3.7 Flash, Claude Opus 5, Claude Sonnet 5 and GPT-5.6, plus pricing and where it loses.
Read Tutorial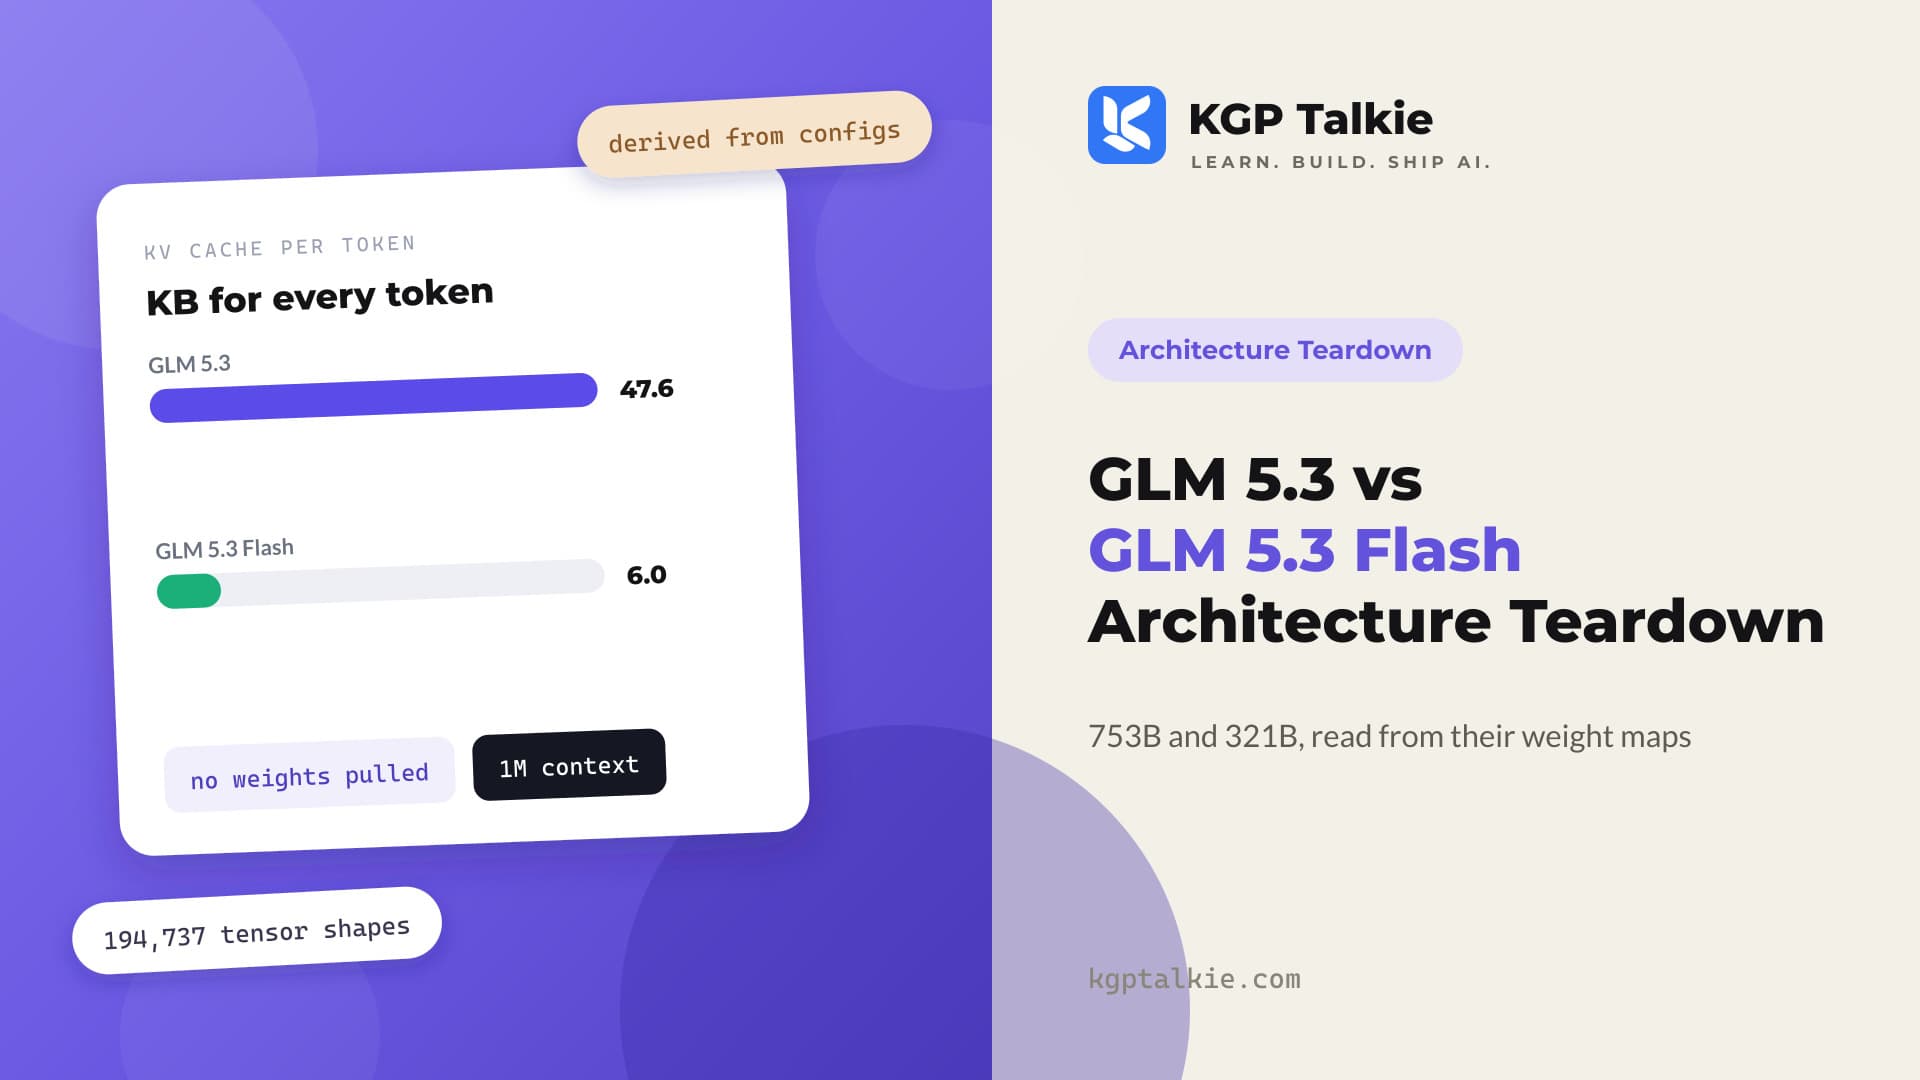
GLM 5.3 vs GLM 5.3 Flash Architecture Teardown
We read the config files and every tensor shape of GLM 5.3 and GLM 5.3 Flash without downloading the weights, and worked out why the smaller model caches eight times less for each token.
Read Tutorial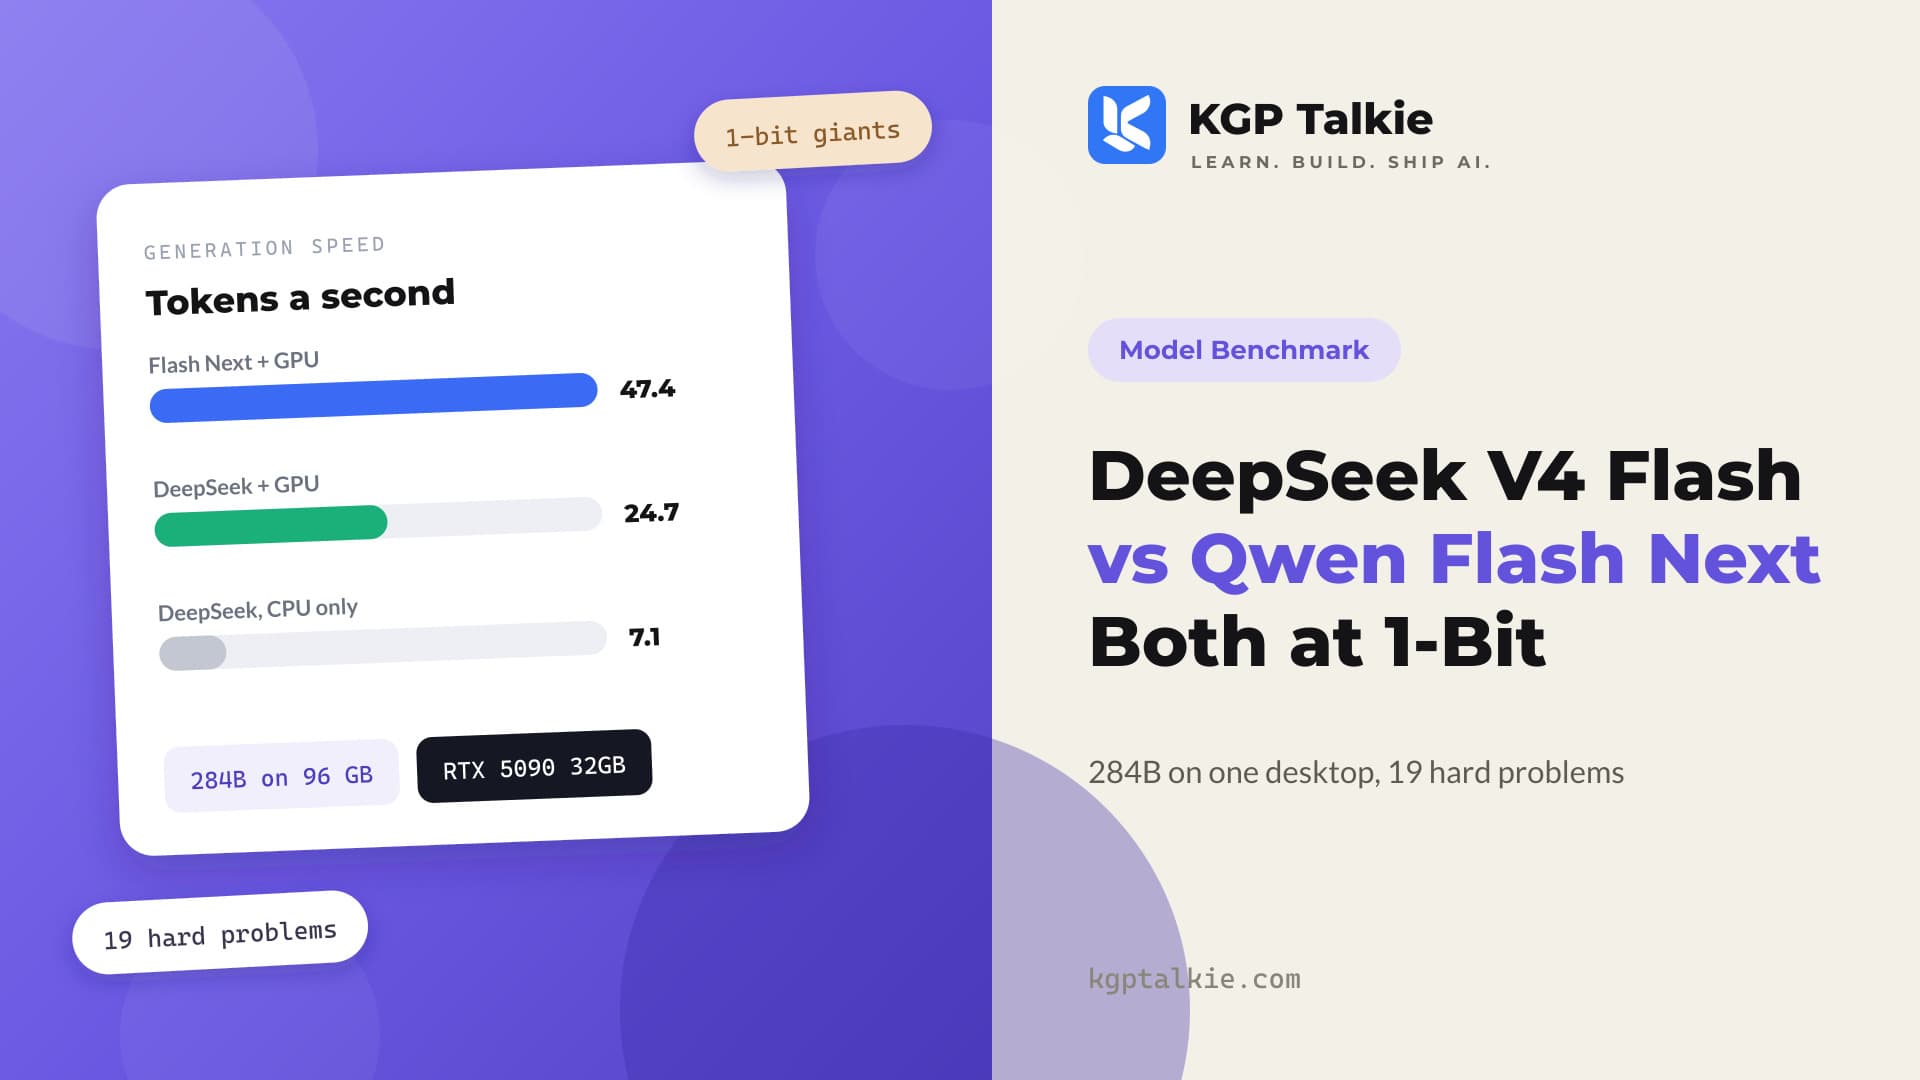
I Ran 1-bit DeepSeek V4 Flash and Qwen 3.8 Flash Next on CPU (No GPU Needed)
We ran DeepSeek V4 Flash and Qwen 3.8 Flash Next, both at 1-bit, on 19 hard problems on one RTX 5090 desktop. The score gap is about finishing, not reasoning.
Read Tutorial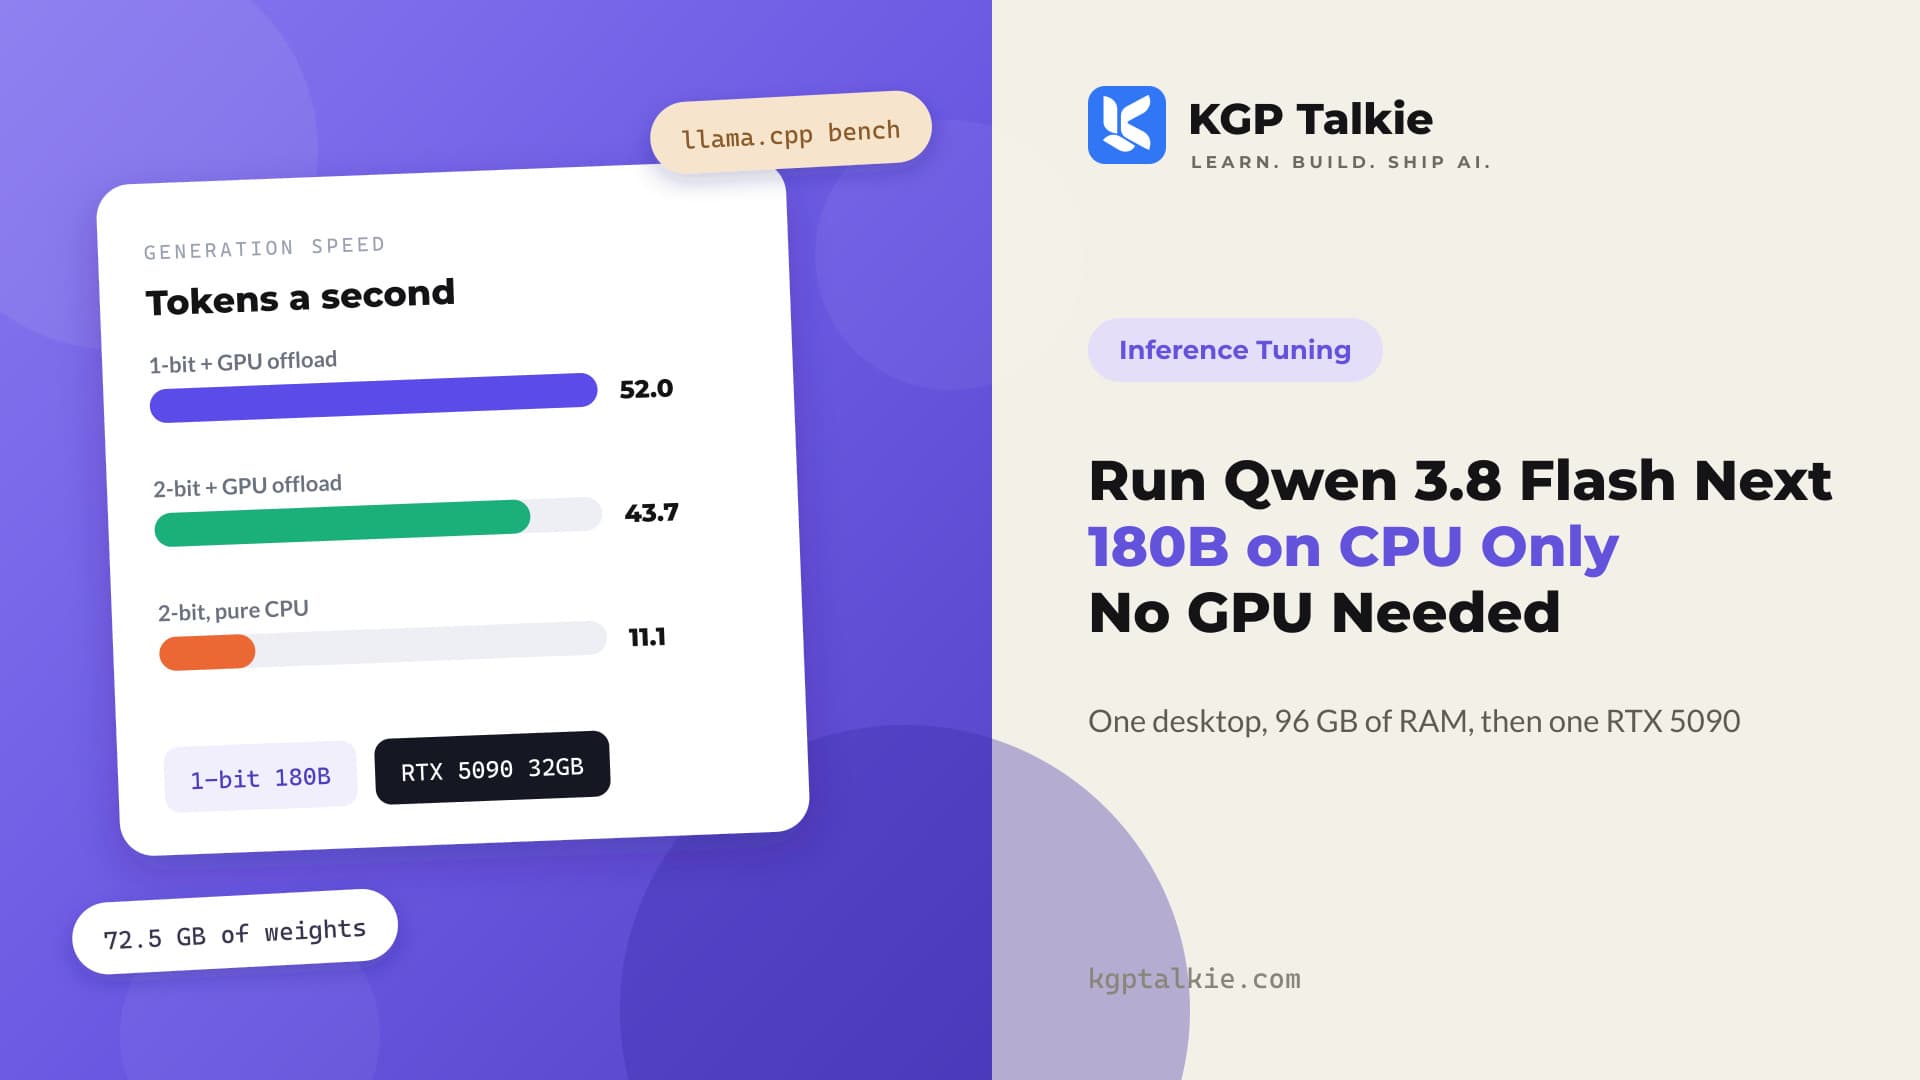
Run Qwen 3.8 Flash Next (Qwen 4) 180B on CPU Only, No GPU Needed
We ran the 180B Qwen3.8-Flash-Next on one desktop with no GPU at all, then added a single RTX 5090, and measured speed and answer quality against Qwen 3.8 27B.
Read Tutorial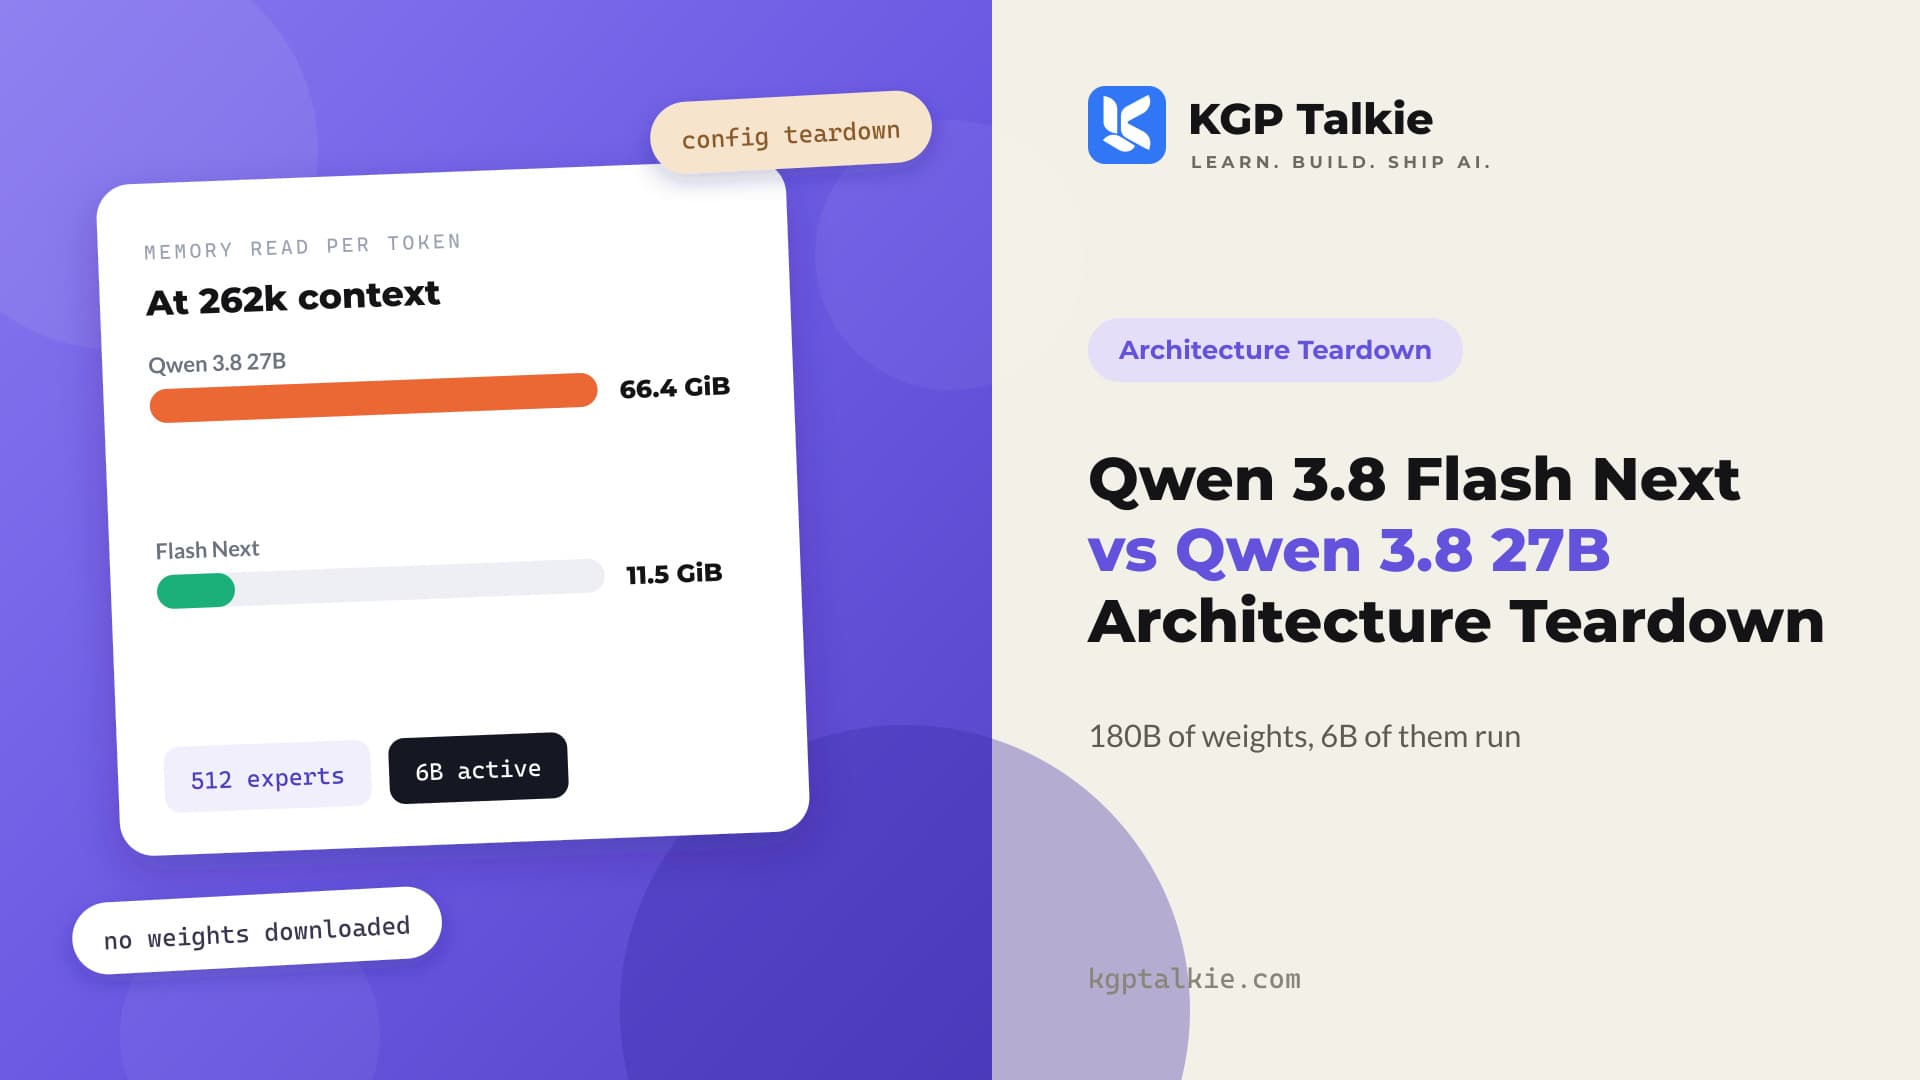
Qwen 3.8 Flash Next (Qwen 4) vs Qwen 3.8 27B Architecture Teardown
We read the config files and weight maps of Qwen3.8-Flash-Next and Qwen 3.8 27B to find the four changes that let a 180B model run only 6B of its weights per token.
Read Tutorial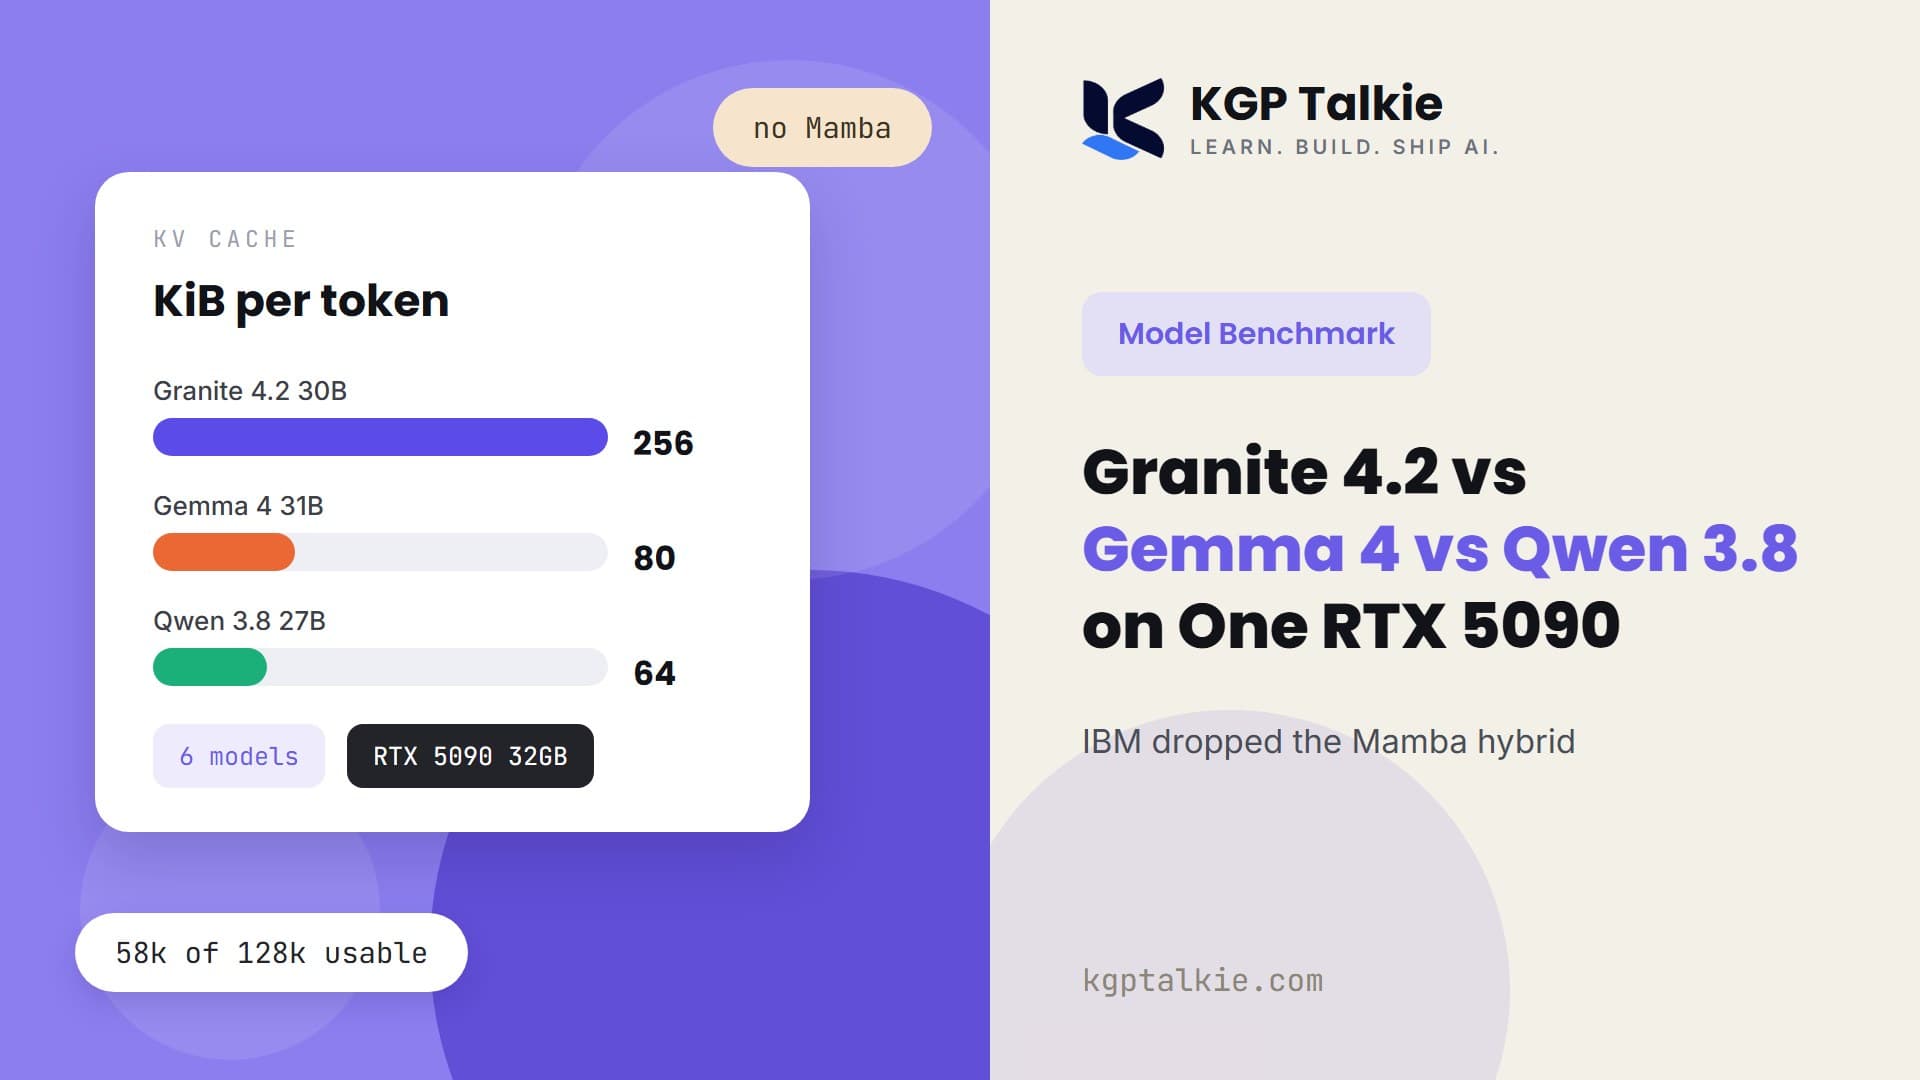
Granite 4.2 vs Gemma 4 vs Qwen 3.8 Benchmark
IBM dropped the Mamba hybrid in Granite 4.2. We measured what that costs against Gemma 4, Qwen 3.8 and Ornith 1.5 on one RTX 5090.
Read Tutorial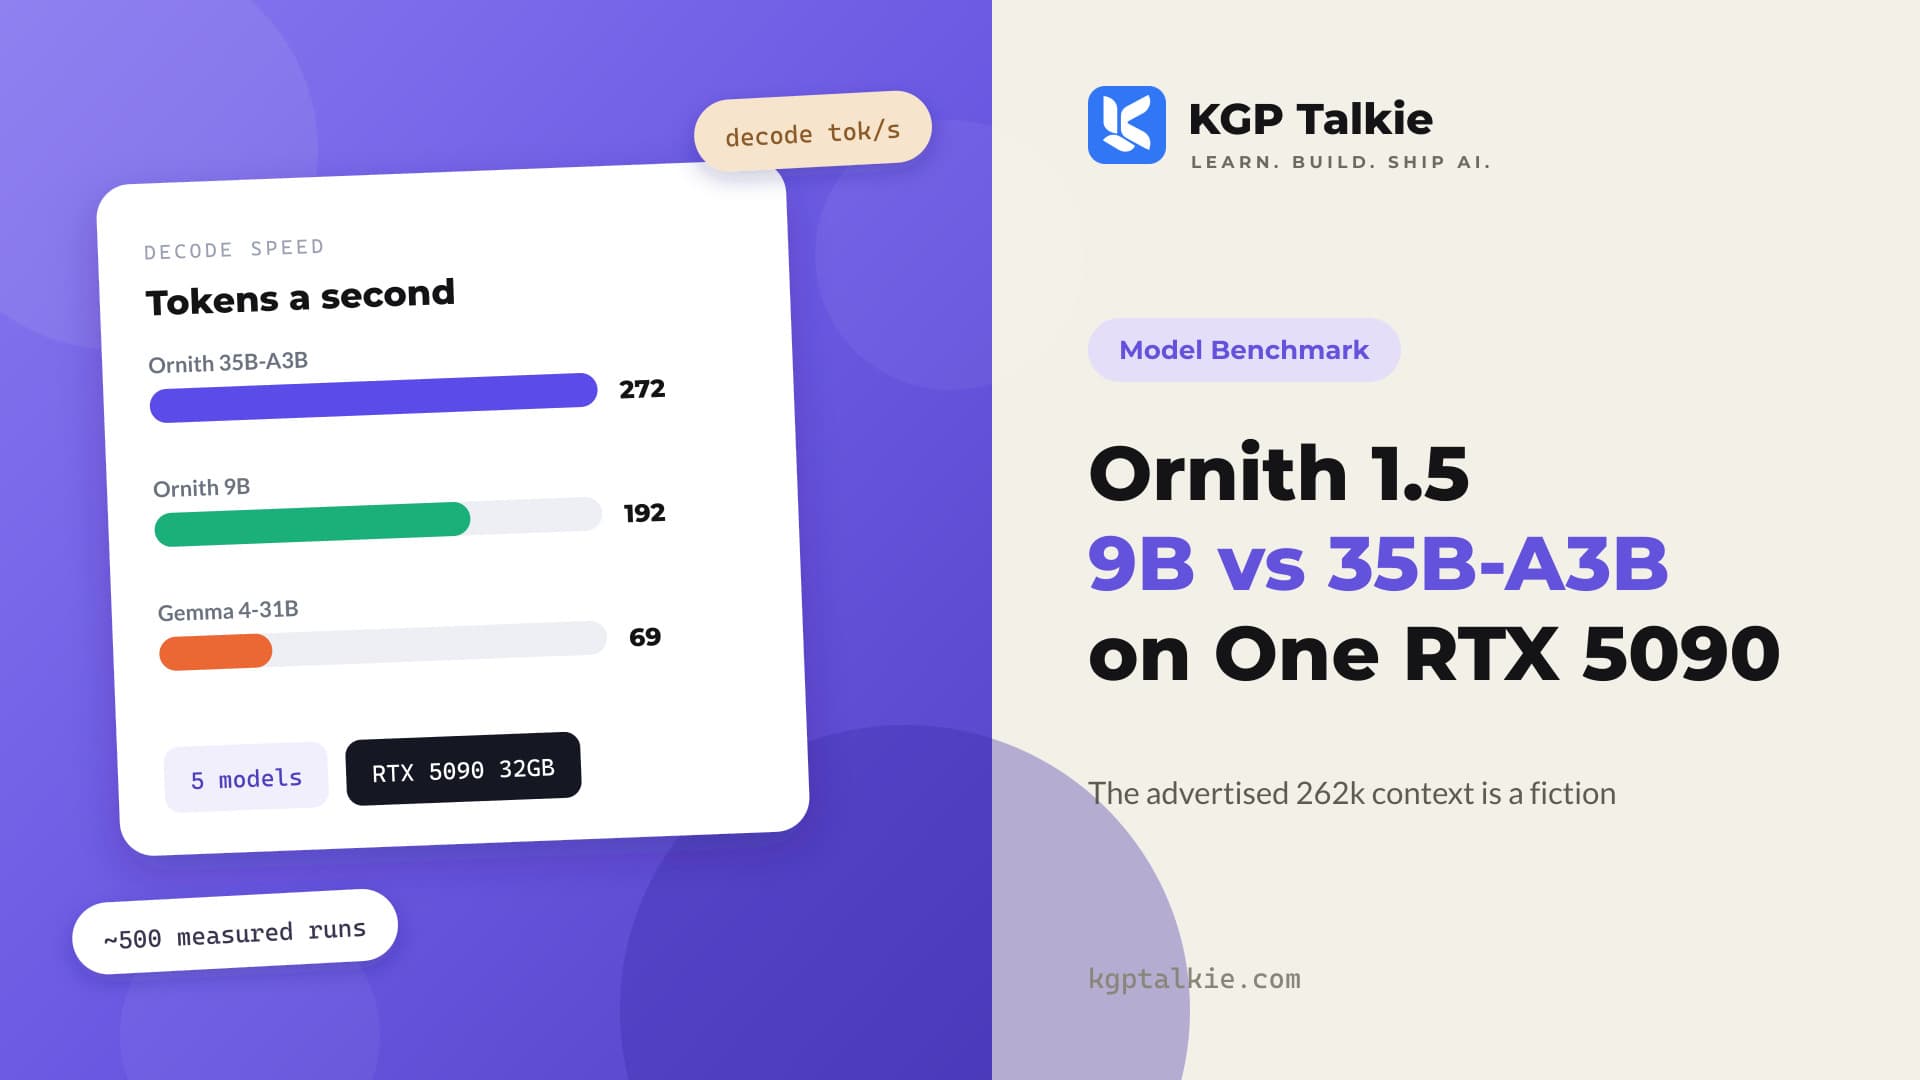
Ornith 1.5 9B and 35B-A3B Benchmark on RTX 5090
We benchmarked Ornith 1.5 9B and 35B-A3B against Gemma 4-26B-A4B and Qwen 3.8 27B on one RTX 5090, and found the two mixtures are nearly identical on hardware and separated entirely by training.
Read Tutorial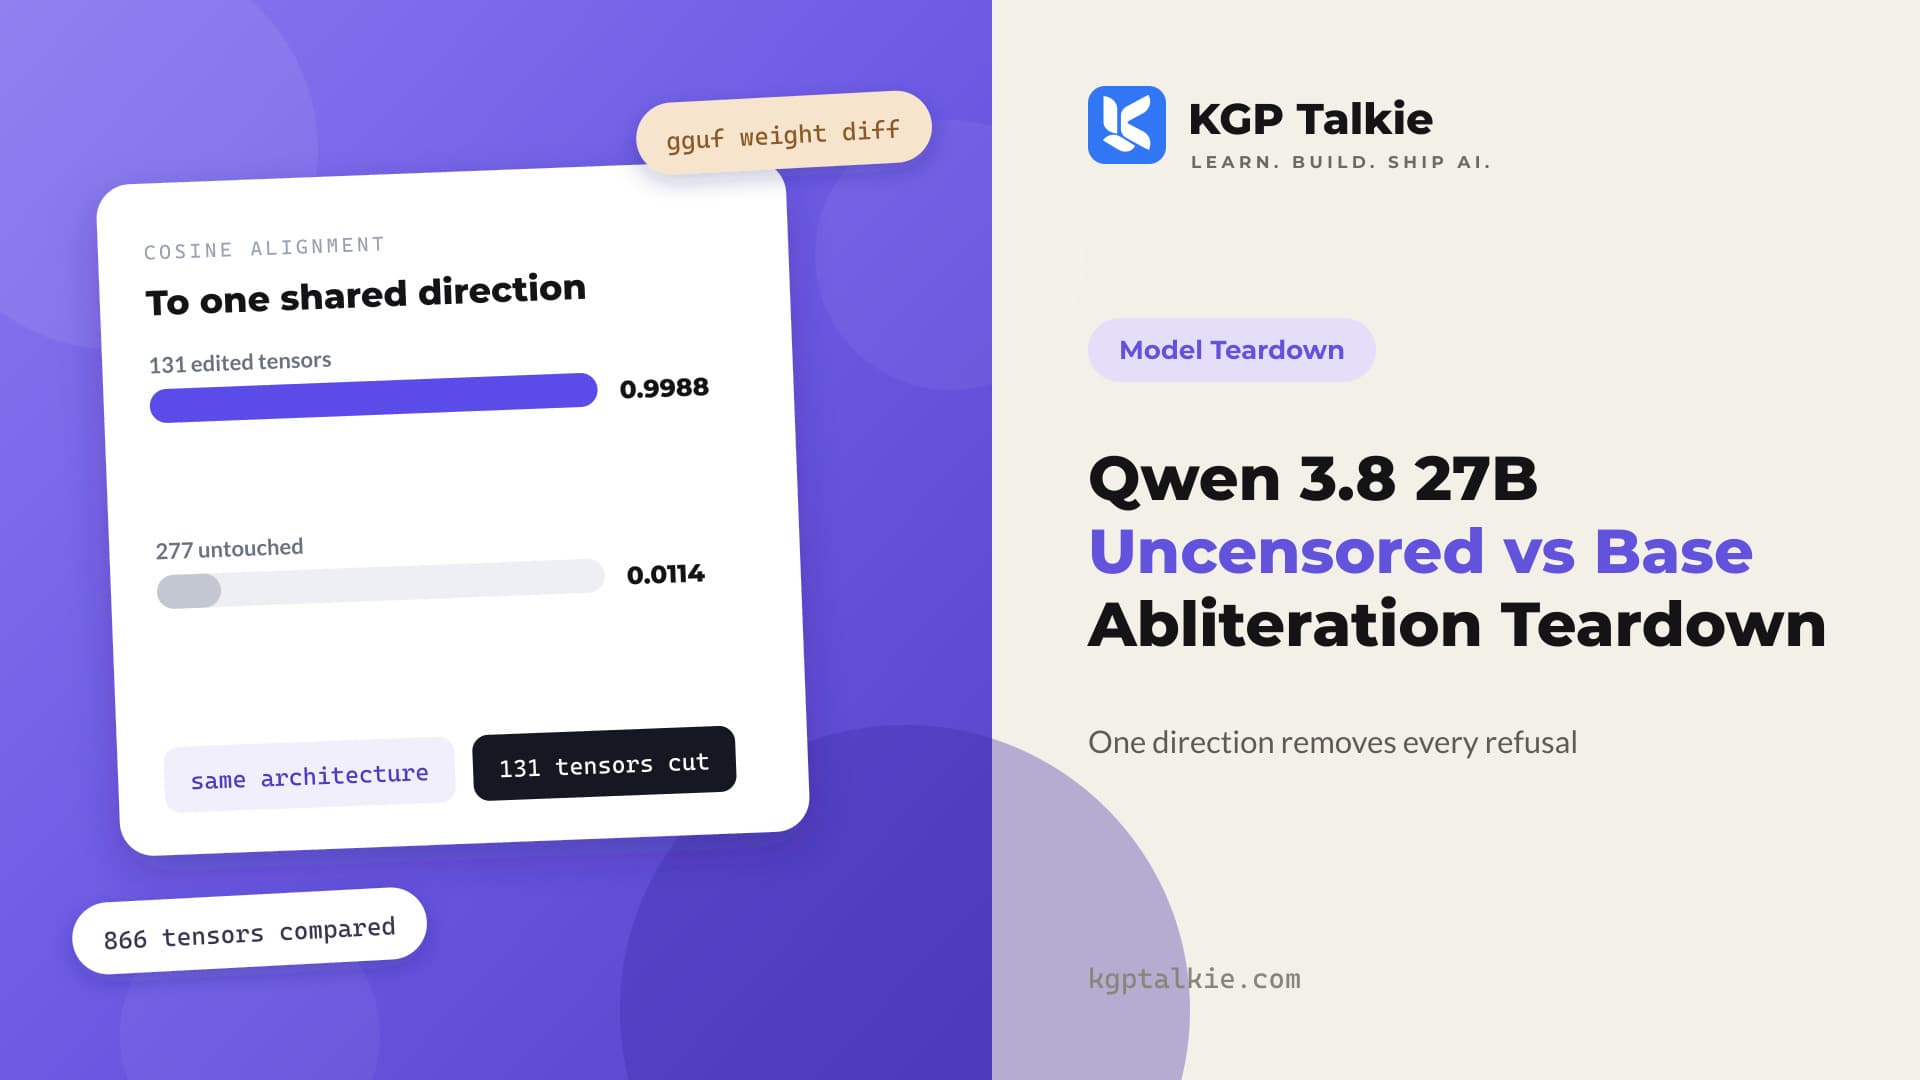
Qwen 3.8 27B Uncensored vs Base Abliteration Teardown
We diffed all 866 GGUF tensors of an uncensored Qwen 3.8 27B against the original and found 131 matrices edited along one shared direction, with no measurable cost to quality.
Read Tutorial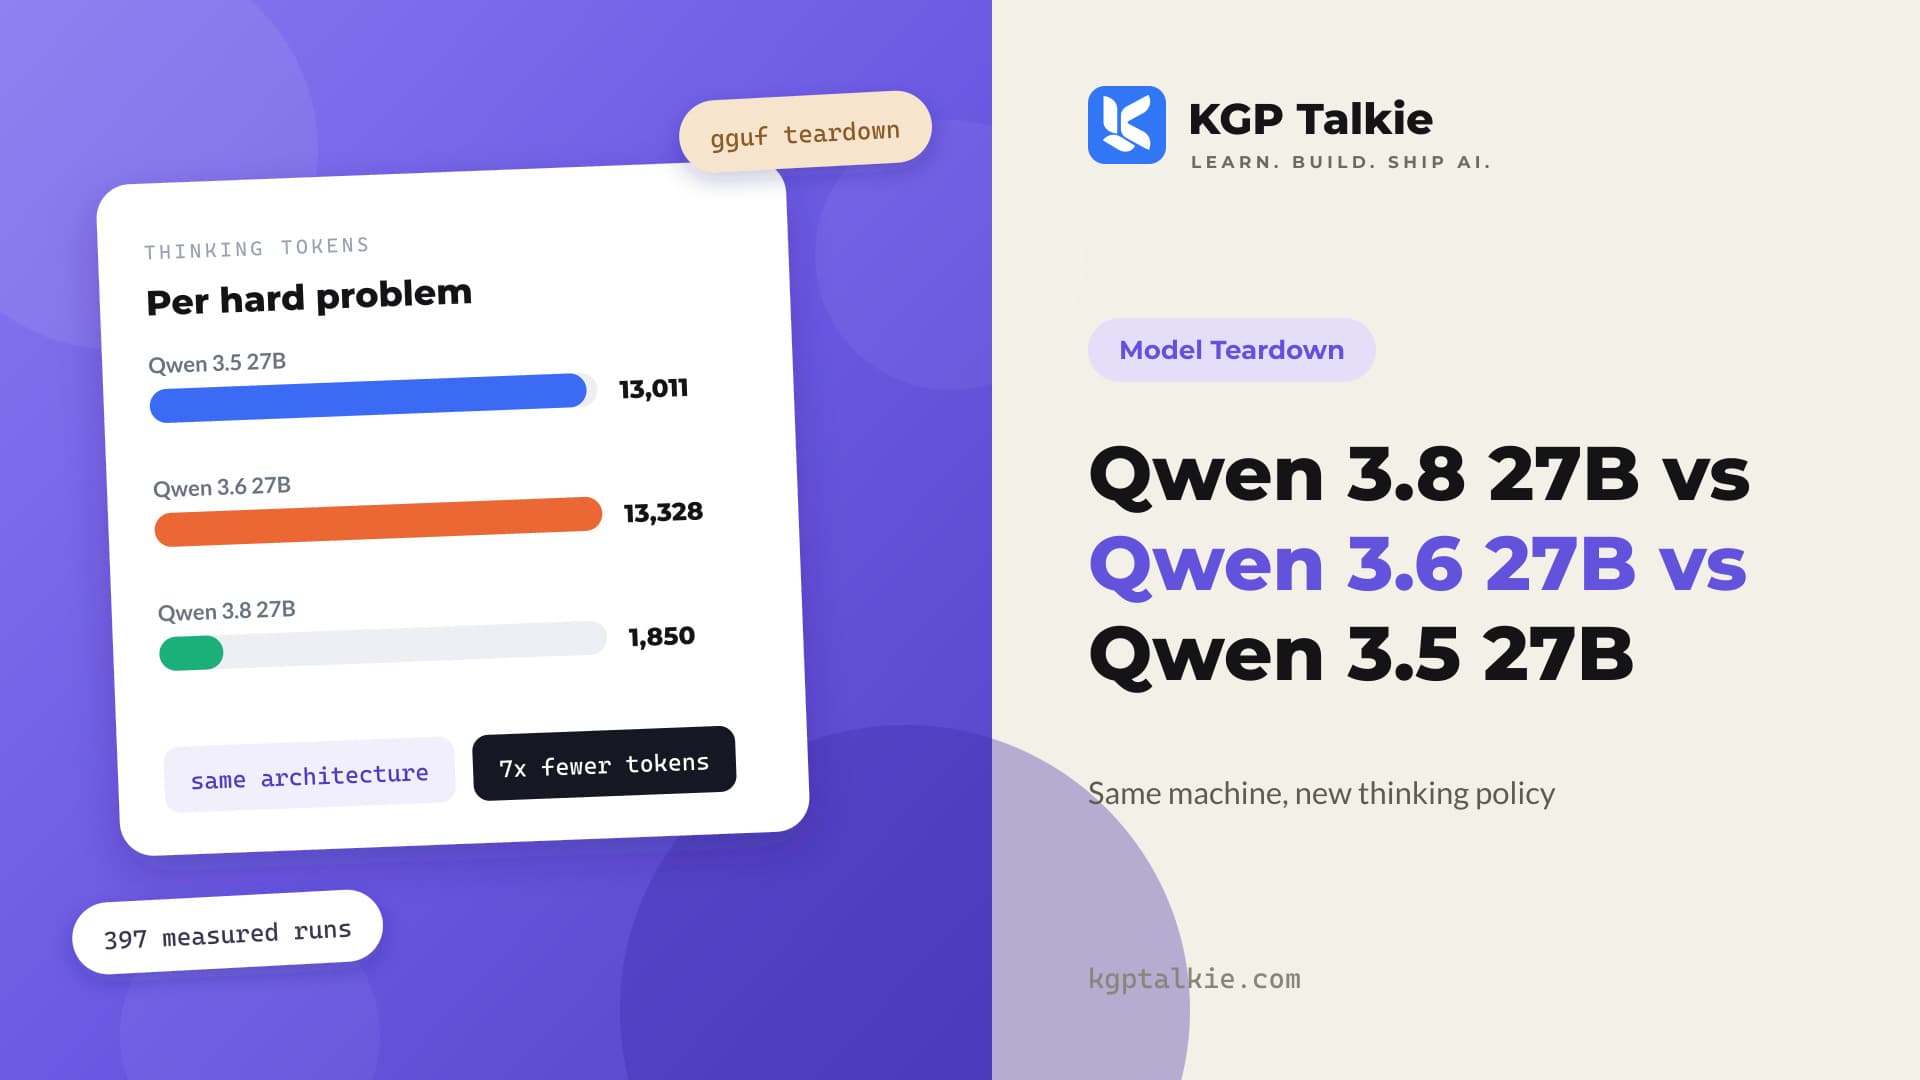
Qwen 3.8 27B vs Qwen 3.6 27B vs Qwen 3.5 27B Teardown
We read the GGUF headers of Qwen 3.8 27B, Qwen 3.6 27B, and Qwen 3.5 27B and ran 397 measured generations on one RTX 5090 to find where the gains between the three releases really come from.
Read Tutorial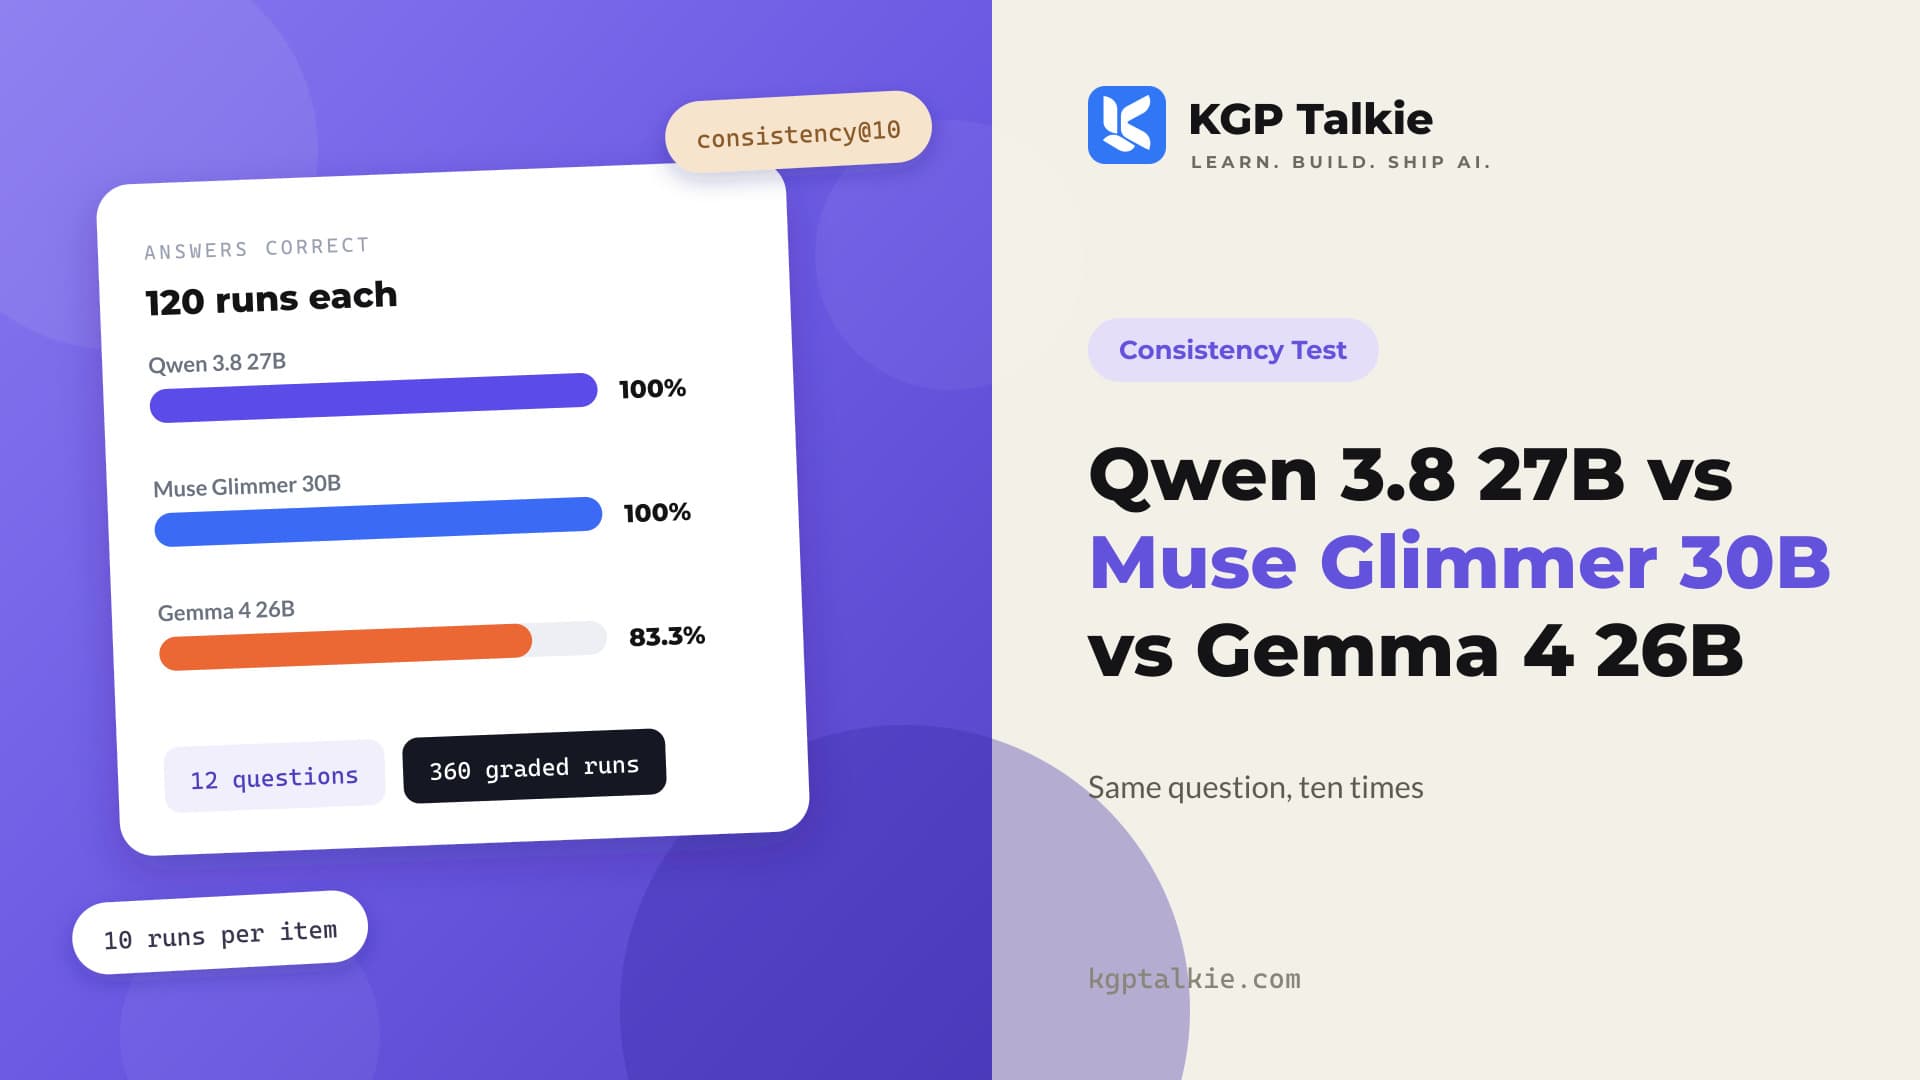
Qwen 3.8 27B vs Muse Glimmer 30B vs Gemma 4 26B Consistency Test
We asked Qwen 3.8 27B, Muse Glimmer 30B, and Gemma 4 26B the same twelve questions ten times each on one RTX 5090 to measure which local model gives the same answer twice.
Read Tutorial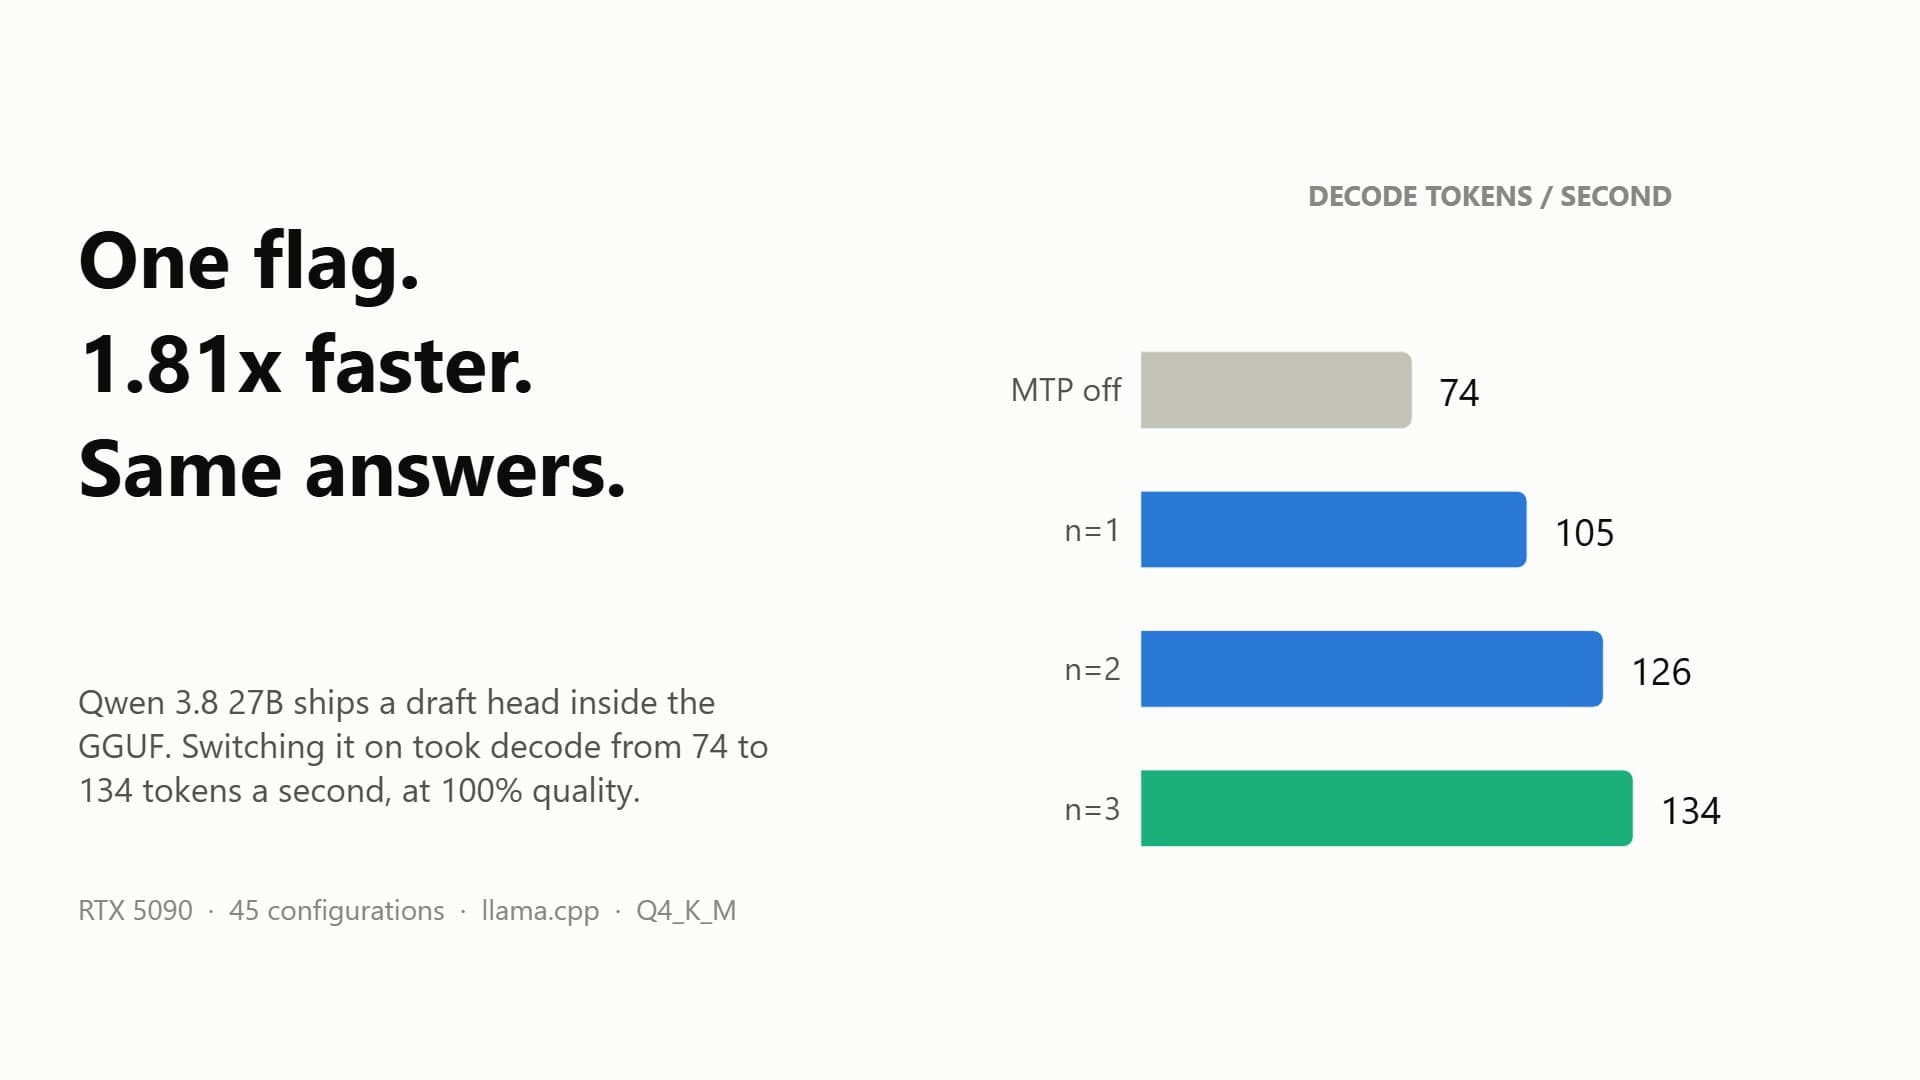
Qwen 3.8 27B Speed Settings on llama.cpp
We ran 45 llama.cpp configurations of Qwen 3.8 27B on one RTX 5090 to find which settings make it faster: draft depth, KV cache type, context size, and reasoning effort.
Read Tutorial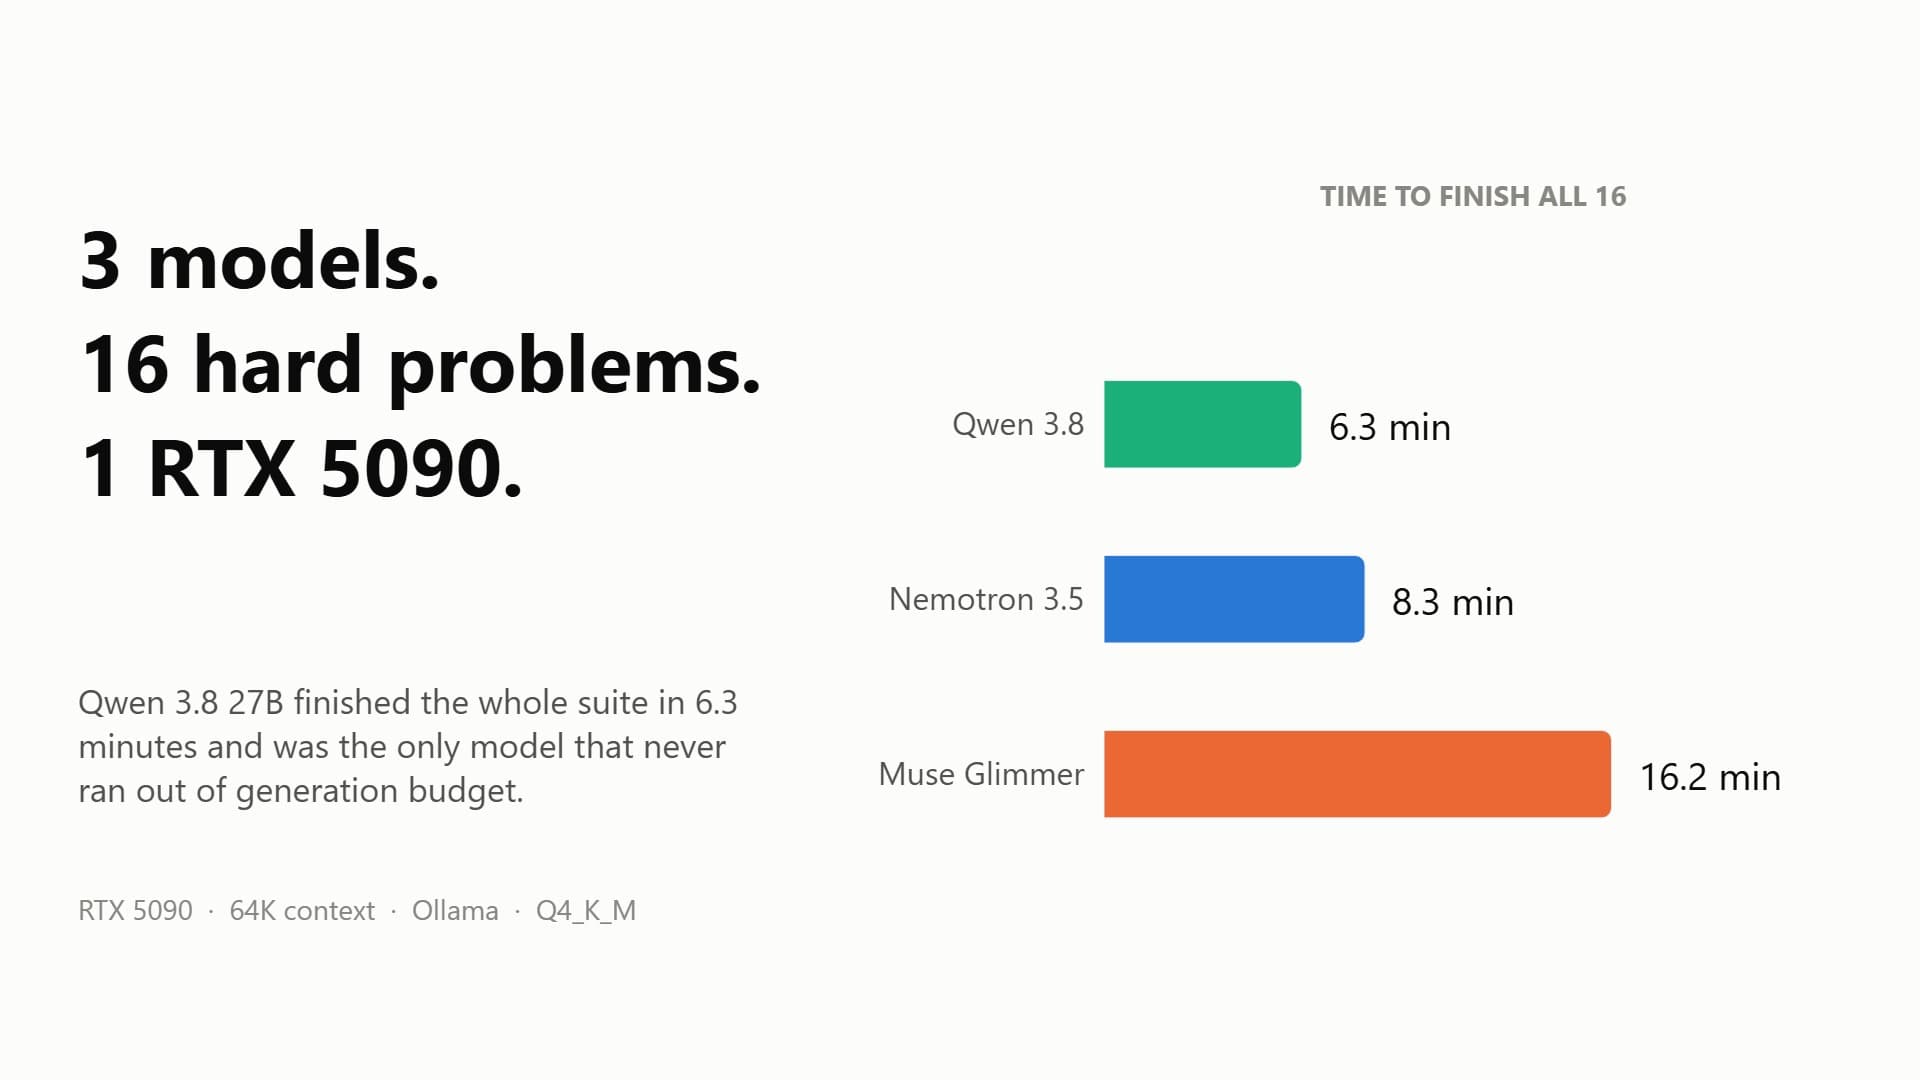
Qwen 3.8 27B vs Nemotron 3.5 vs Muse Glimmer on an RTX 5090
We ran Qwen 3.8 27B, Nemotron 3.5 Lightning, and Muse Glimmer on sixteen hard problems on one RTX 5090 to compare accuracy, speed, VRAM, and how each model fails.
Read Tutorial
Grok 4.6 vs Gemini 3.7 Flash on Benchmarks and Pricing
Grok 4.6 vs Gemini 3.7 Flash compared on the four benchmarks both companies actually publish, plus pricing, the FrontierCode label trap, and which model fits which workload.
Read Tutorial
Nemotron 3.5 vs Muse Glimmer 30B on an RTX 5090
Hands-on benchmark of NVIDIA Nemotron 3.5 Lightning vs Meta Muse Glimmer 30B on one RTX 5090 with Ollama: generation speed, VRAM use, and long-context behavior.
Read Tutorial
Advanced LLM Benchmark Prompt Suite
A comprehensive guide on progressive benchmarking for Large Language Models using structured prompt architectures and high-quality browser-based tests.
Read Tutorial
Local LLMs 2026: Technical Reference
A detailed technical guide comparing dense, sparse MoE, and hybrid SSM local LLM architectures for optimal deployment on 24GB VRAM hardware systems in 2026.
Read Tutorial